展开查看完整源码run.py · 101 行
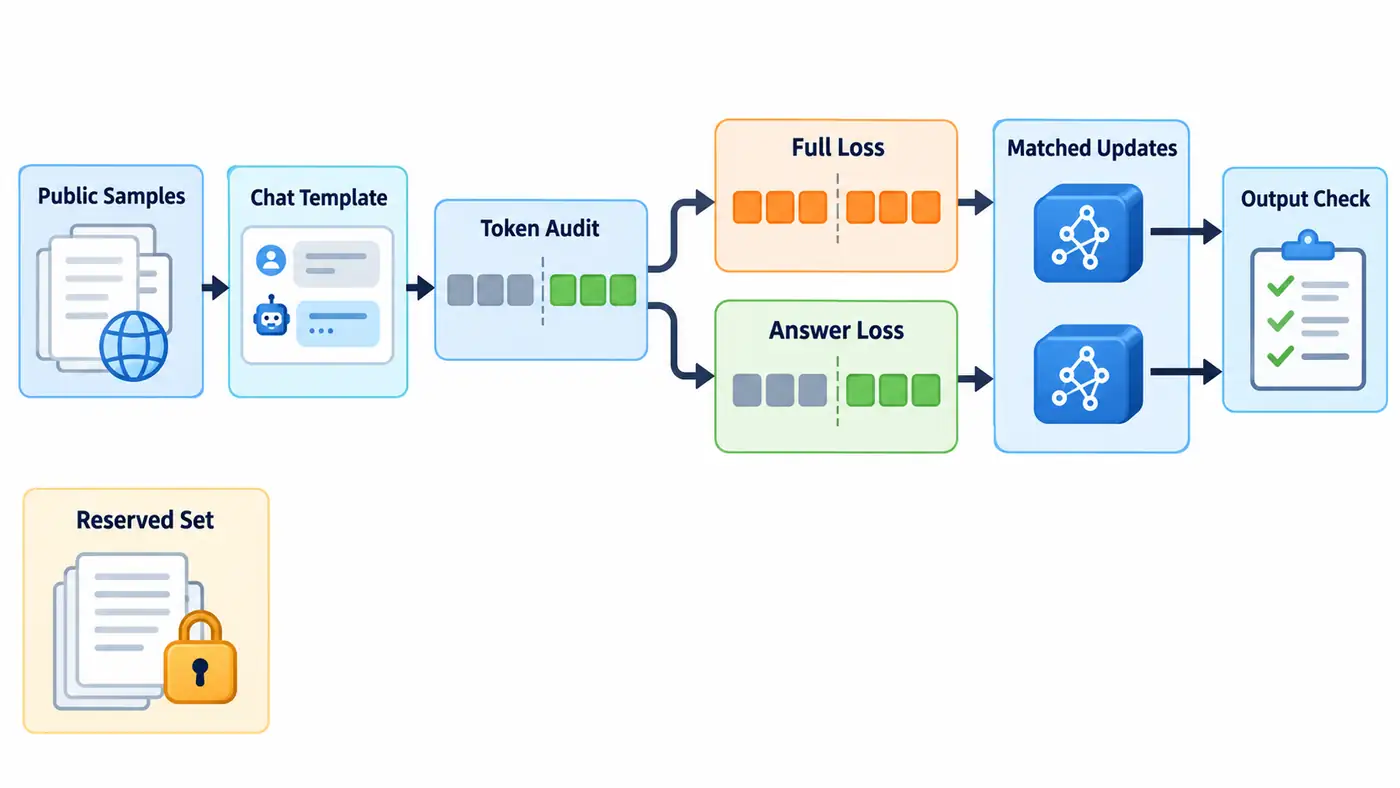
"""Real SmolLM2 SFT mask audit; tiny diagnostic, not benchmark training."""
import argparse, gc, hashlib, json, pathlib, platform, resource, sys, time, traceback
from prepare import ROOT, digest, prepare
from scoring import score, aggregate

def save(p,x):p.write_text(json.dumps(x,ensure_ascii=False,indent=2)+'\n')
def sha(x):return hashlib.sha256(x.encode()).hexdigest()
def ordered(rows,s):return sorted(rows,key=lambda r:sha(f'{s}:{r["idx"]}'))
def message(c,k,s):return [{'role':'system','content':c['system']},{'role':'user','content':c['task']+'\n'+c['contracts'][k]+'\nReview: '+s}]
def build(tok,c,row):
    msgs=message(c,'json',row['sentence']); prefix=tok.apply_chat_template(msgs,tokenize=True,add_generation_prompt=True)
    target=json.dumps({'sentiment':('negative','positive')[row['label']]})
    full=tok.apply_chat_template(msgs+[{'role':'assistant','content':target}],tokenize=True,add_generation_prompt=False)
    assert full[:len(prefix)]==prefix,'Boundary token merge: do not infer a mask from separate text lengths'
    eos=full.index(tok.eos_token_id,len(prefix)); assert tok.decode(full[len(prefix):eos])==target
    ids=full[:eos+1];assert len(ids)<=c['max_train_tokens'],'Truncated response prohibited'
    return {'idx':row['idx'],'gold':row['label'],'ids':ids,'prefix':len(prefix),'eos':eos,'template_tail_removed':full[eos+1:],'sentence_sha256':sha(row['sentence'])}
def collate(rows,arm,pad):
    import torch
    width=max(len(r['ids']) for r in rows);ids=torch.full((len(rows),width),pad,dtype=torch.long);att=torch.zeros_like(ids);lab=torch.full_like(ids,-100)
    for i,r in enumerate(rows):
        n=len(r['ids']);ids[i,:n]=torch.tensor(r['ids']);att[i,:n]=1;lab[i,:n]=ids[i,:n]
        if arm=='assistant':lab[i,:r['prefix']]=-100
        assert lab[i,r['eos']]==pad # real EOS remains despite EOS==PAD
        assert (lab[i,n:]==-100).all()
    return {'input_ids':ids,'attention_mask':att,'labels':lab}
def evaluate(model,tok,c,rows,stage):
    import torch
    from transformers import GenerationConfig
    gen=GenerationConfig(**c['decoding'],eos_token_id=tok.eos_token_id,pad_token_id=tok.pad_token_id,bos_token_id=tok.bos_token_id)
    model.eval();records=[]
    with torch.inference_mode():
        for r in rows:
            for k in ('plain','json'):
                text=tok.apply_chat_template(message(c,k,r['sentence']),tokenize=False,add_generation_prompt=True)
                x=tok(text,add_special_tokens=False,return_tensors='pt');assert x.input_ids.shape[1]<=c['max_input_tokens']
                start=time.perf_counter();y=model.generate(**x,generation_config=gen)[0,x.input_ids.shape[1]:].tolist();out=tok.decode(y,skip_special_tokens=True)
                records.append({'stage':stage,'idx':r['idx'],'gold':r['label'],'contract':k,'prompt_sha256':sha(text),'input_length':x.input_ids.shape[1],'generated_ids':y,'output':out,'stop':'eos' if y[-1]==tok.eos_token_id else 'length','seconds':time.perf_counter()-start,**score(out,k,r['label'])})
    return records

def main(a):
    import torch,transformers,pyarrow.parquet as pq
    from transformers import AutoTokenizer,AutoModelForCausalLM
    start=time.perf_counter();c=json.loads((ROOT/'config.json').read_text());torch.set_num_threads(c['threads']);torch.manual_seed(c['seed']);lock=prepare(a.cache)
    stages={'download':'passed; all hash locked resources verified','preprocessing':'running','training':'pending','evaluation':'pending'};save(a.out/'stages.json',stages)
    dp=a.cache/'sst2'/lock['data']['revision']/'data';train=ordered(pq.read_table(dp/'train-00000-of-00001.parquet').to_pylist(),c['seed'])[:c['train_count']]
    val=ordered(pq.read_table(dp/'validation-00000-of-00001.parquet').to_pylist(),c['split_seed']);dev=val[:c['eval_count']];reserved=val[c['count']:c['count']+c['confirmation_count']]
    norm=lambda s:' '.join(s.lower().split());assert not {norm(r['sentence']) for r in train}&{norm(r['sentence']) for r in dev+reserved}
    split={'train':[r['idx'] for r in train],'development':[r['idx'] for r in dev],'confirmation_reserved':[r['idx'] for r in reserved],'train_validation_exact_overlap':0,'smoke':a.smoke}
    if a.smoke:train=train[:2];dev=dev[:2]
    split.update(executed_train=[r['idx'] for r in train],executed_development=[r['idx'] for r in dev]);save(a.out/'split.json',split)
    md=a.cache/'models'/lock['model']['revision'];tok=AutoTokenizer.from_pretrained(md,local_files_only=True);rows=[build(tok,c,r) for r in train]
    identity={'config':c,'resources':lock,'split':split,'chat_template_sha256':sha(tok.chat_template),'code_hashes':{n:digest(ROOT/n) for n in ['run.py','prepare.py','scoring.py','config.json','resources.lock.json','PROTOCOL.md']}}
    identity['cache_key']=sha(json.dumps(identity,sort_keys=True));save(a.out/'identity.json',identity)
    audits=[];raw=[]
    for r in rows:
        positions=[]
        for j,t in enumerate(r['ids']):positions.append({'position':j,'region':'prompt' if j<r['prefix'] else ('eos' if j==r['eos'] else 'answer'),'full_label_active':j>0,'assistant_label_active':j>=r['prefix']})
        audits.append({k:v for k,v in r.items() if k!='ids'}|{'sequence_length':len(r['ids']),'positions':positions,'truncation':[{'limit':lim,'retained_answer_targets':max(0,min(lim,len(r['ids']))-r['prefix']),'lost_targets':len(r['ids'])-max(r['prefix'],min(lim,len(r['ids']))),'eos_retained':lim>r['eos']} for lim in c['truncation_audit_lengths']]})
        raw.append(r|{'tokens':tok.convert_ids_to_tokens(r['ids'])})
    save(a.out/'mask_audit.json',audits);a.private.mkdir(parents=True,exist_ok=True);save(a.private/(a.out.name+'-token_trace.json'),raw)
    stages['preprocessing']='passed; prefix identity, answer/EOS, overlap, masks, truncation audited';save(a.out/'stages.json',stages)
    predictions=[];steps=[];checks=[];checkpoints=[];arm_metrics={}
    for arm in ('full','assistant'):
        torch.manual_seed(c['seed']);model=AutoModelForCausalLM.from_pretrained(md,local_files_only=True,torch_dtype=torch.float32,attn_implementation='eager');model.config.use_cache=False
        if arm=='full':
            before=evaluate(model,tok,c,dev,'before');predictions+=before;arm_metrics['before']=aggregate(before)
        # No dropout randomness: eval-mode autograd is intentional, not inference_mode.
        model.eval();opt=torch.optim.SGD(model.parameters(),lr=c['lr'],momentum=0,weight_decay=0)
        before_probe=model.model.layers[0].self_attn.q_proj.weight.detach().clone();ttrain=time.perf_counter()
        for step in range(len(rows)//c['batch_size']):
            rr=rows[step*c['batch_size']:(step+1)*c['batch_size']];batch=collate(rr,arm,tok.pad_token_id);opt.zero_grad(set_to_none=True)
            embeds=model.get_input_embeddings()(batch['input_ids']);embeds.retain_grad()
            out=model(inputs_embeds=embeds,attention_mask=batch['attention_mask'],labels=batch['labels'],use_cache=False);out.logits.retain_grad()
            shifted=batch['labels'][:,1:];valid=shifted!=-100
            manual=torch.nn.functional.cross_entropy(out.logits[:,:-1,:].reshape(-1,out.logits.shape[-1]),shifted.reshape(-1),ignore_index=-100,reduction='sum')/valid.sum()
            err=abs(out.loss.item()-manual.item());assert err<2e-6
            out.loss.backward();g=out.logits.grad[:,:-1,:];ignored=g[~valid].abs().max().item() if (~valid).any() else 0.0
            active=g[valid].abs().sum().item();assert ignored==0 and active>0
            prompt_grad=embeds.grad[0,:rr[0]['prefix']].abs().sum().item();assert prompt_grad>0
            # First answer target is predicted at prefix-1; final EOS at eos-1.
            for i,r in enumerate(rr):assert shifted[i,r['prefix']-1]==r['ids'][r['prefix']] and shifted[i,r['eos']-1]==tok.eos_token_id
            norm=torch.nn.utils.clip_grad_norm_(model.parameters(),c['clip_norm']).item();assert 0<norm<float('inf');opt.step()
            rec={'arm':arm,'step':step+1,'idx':[r['idx'] for r in rr],'loss':out.loss.item(),'manual_ce':manual.item(),'difference':err,'supervised_tokens':int(valid.sum()),'input_tokens':int(batch['attention_mask'].sum()),'padding_tokens':int((batch['attention_mask']==0).sum()),'gradient_norm_before_clip':norm,'clip_scale':min(1,c['clip_norm']/(norm+1e-6)),'ignored_logit_grad_max':ignored,'active_logit_grad_l1':active,'prompt_embedding_grad_l1':prompt_grad,'input_shape':list(batch['input_ids'].shape),'logits_shape':list(out.logits.shape)}
            steps.append(rec);print(json.dumps(rec),flush=True)
            del out,manual,embeds,g,batch
            if time.perf_counter()-start>c['walltime_budget_seconds']:raise TimeoutError('budget exceeded')
        train_seconds=time.perf_counter()-ttrain;delta=(model.model.layers[0].self_attn.q_proj.weight-before_probe).abs().max().item();assert delta>0
        checkpoint=a.private/(a.out.name+'-'+arm+'-state.pt');torch.save(model.state_dict(),checkpoint)
        checkpoints.append({'arm':arm,'filename':checkpoint.name,'sha256':digest(checkpoint),'bytes':checkpoint.stat().st_size,'q_proj_max_abs_change':delta,'training_seconds':train_seconds,'parameters':sum(p.numel() for p in model.parameters())})
        model.zero_grad(set_to_none=True);after=evaluate(model,tok,c,dev,arm);predictions+=after;arm_metrics[arm]=aggregate(after)
        del model,opt,before_probe;gc.collect()
    (a.out/'predictions.jsonl').write_text(''.join(json.dumps(x,ensure_ascii=False)+'\n' for x in predictions));save(a.out/'steps.json',steps);save(a.out/'summary.json',arm_metrics);save(a.out/'checkpoints.json',checkpoints)
    rss=resource.getrusage(resource.RUSAGE_SELF).ru_maxrss*(1 if sys.platform=='darwin' else 1024);assert rss<c['rss_budget_bytes']
    save(a.out/'environment.json',{'os':platform.platform(),'python':platform.python_version(),'torch':torch.__version__,'transformers':transformers.__version__,'device':'cpu','dtype':'float32','threads':torch.get_num_threads(),'seconds_after_imports':time.perf_counter()-start,'peak_rss_bytes':rss,'gpu_memory':'not measured; CPU only'})
    stages.update(training='passed; both arms, all parameters, four steps each (smoke one)',evaluation='passed; before and both final states, development only',exit_code=0);save(a.out/'stages.json',stages)

if __name__=='__main__':
    ap=argparse.ArgumentParser();ap.add_argument('--cache',type=pathlib.Path,required=True);ap.add_argument('--out',type=pathlib.Path,required=True);ap.add_argument('--private',type=pathlib.Path,required=True,help='local token traces and weights; exclude from distribution');ap.add_argument('--smoke',action='store_true');a=ap.parse_args();a.out.mkdir(parents=True,exist_ok=False)
    try:main(a)
    except Exception as e:save(a.out/'failure.json',{'error':str(e),'type':type(e).__name__,'exit_code':1});traceback.print_exc();sys.exit(1)