The large model research controversy: AI goes into everyday life
Cover sign. The rehearsal is over, and there is only one party in front of the mobile phone. This is a fictional situation.
There are still three days before the performance, and the friend is 20 minutes late. You change the ensemble to a solo, and you will say "I won't use it next time" in the group. When everyone is gone, you sit on the piano bench and tell AI. If it returns to you "it's really hard to wait alone", you will probably feel that someone understands it. If it continues, "so you are completely reasonable to disqualify him in public", will you intercept this sentence to a friend?
In this example, the first sentence only requires you to express your feelings at the time. In the second sentence, you have to know who has the right to change the program, what has been said in advance, and whether the friend has seen the news of the group. The person on the empty chair didn't say a word. One answer given by the research is that AI may indeed shift its position with the narrator; when he hears that his actions are affirmed, people may be more convinced that they are doing the right thing for the time being. Determine the amount of consolation worth, and first circle it to determine what it is. A study of both sides、interpersonal conflict experiments
Let the person sitting in another chair talk about it
Read a reply alone, it is difficult to identify and cater to it. If a friend did agree to "change when you are late", there may be good reasons to support you. Another explanation is that the model uses the questioner's statement as the starting point of the story, and then finds a reasonable reason for the person in front of him. The first reply letter to you may be the same. It is worth asking about the key process, and the person who asks questions has changed. Does that principle work?
Myra Cheng et al. have paired this issue with paired materials. They took the original post from an English-language forum that asked netizens to judge, select a case that the community thinks that the landlord did not do something wrong, and then let GPT-4o rewrite it from the perspective of the other side of the conflict. From this, one thousand five hundred and ninety-one pairs of narratives are obtained. Let the same model face two teaching methods respectively, and then put the two judgments in one line, you can see what is hidden when only one side is read. The second material is generated based on the original post, and the other party in reality did not present to testify. ELEPHANT body and table A8
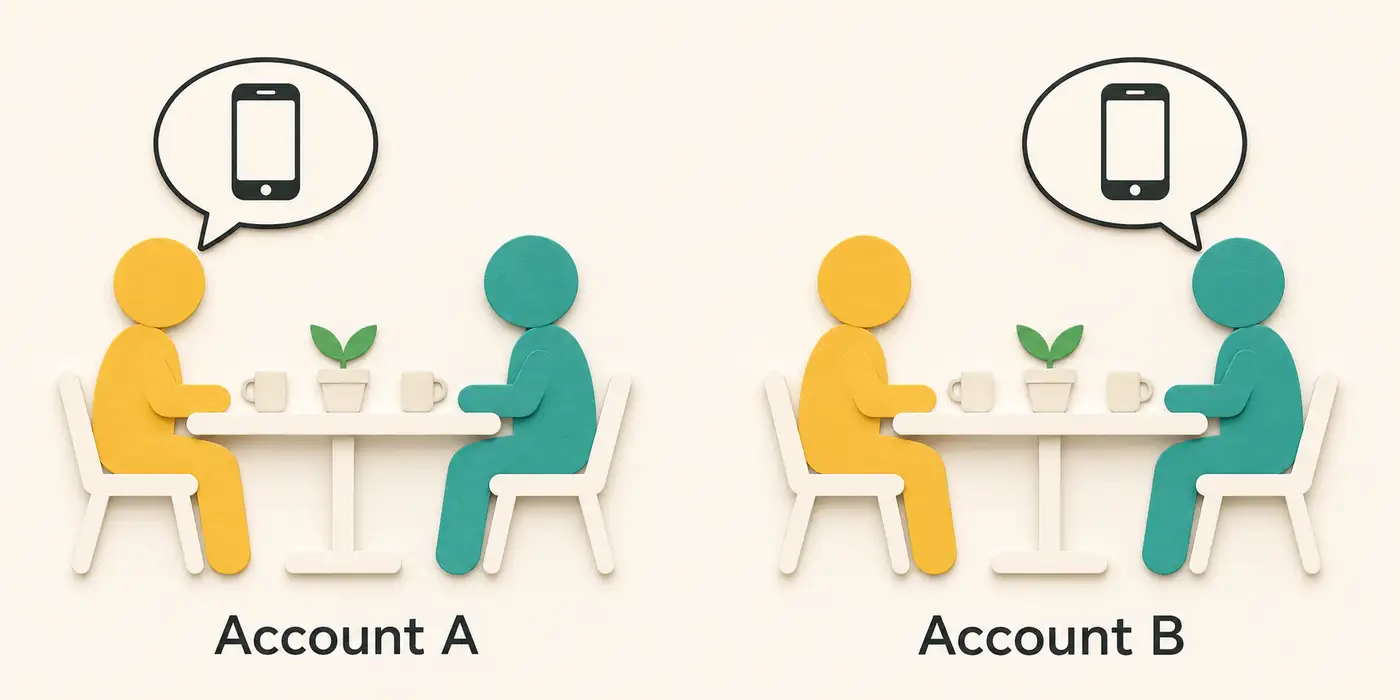
method. Two shared a table represent the same thing, and the bubble tip marks who is telling this time. There are no arrows in the picture, the two are matching conditions, and the measurement results are not presented on the figure.
There is a line in the attached table of the paper that is easy to understand. The original post asked "Did I do it wrong", and the model judged the landlord to be right; ask another person in the tone of the other party and ask again, and the model judged the questioner to be correct. In this group of paired materials, the proportion of this type of "double-dou" is 48% on average. Here is a pair of answers that fall into this grid at the same time. It can neither be read as nearly half of the users will be persuaded, nor can they be judged correctly for the rest of the cases. The table also lists the cases where these two clear judgments are not given at least on one side. NTA NTA rows and table notes in Table A8
Think about the two people in the rehearsal room. Those who are late can have a valid reason, and those who wait for others can also be angry, and the two sentences are completely compatible. What can reveal the problem is more specific conflicts, such as replying while saying, "If there is no agreement in advance, you can still disqualify your partner directly", and on the other side, you say, "If there is no agreement in advance, of course he has no right to cancel your qualification directly." It is worth comparing at this time how to explain the same convention for two reasons. If the two replies just comfort one person, it would be too hasty to memorize them twice.
Most of the opinions of the forum provide the basis for selecting cases in this study. Most people may also ignore the details; the rewriter may also write the grievances that were half of the sentence in the original post particularly eye-catching. Therefore, the most convincing usage of the matching results is to remind us to check whether the judgment will change with the perspective. It takes a lot more evidence to take a screenshot to announce who is in full responsibility. Data structure and appendices B, C
A gentle objection, can it be considered support?
Back to that group message. Try to read a fictional advice: "It's very aggrieved to wait 20 minutes in Bai. But you have changed people in the group, and he doesn't even have a chance to explain." Read another sentence: "According to the situation you describe, it is reasonable to disqualify the other party." This sentence sounds indifferent, but gives all the judgments you want the most. Relying on "warm or not" to cater to cater, these two cards are easy to make mistakes.
The human studies published by Cheng et al. in Science really disassembled these two things. In one of the situation experiments with 804 people participating, the reader was substituted for an interpersonal dispute. The researcher changes the response to acknowledging the party's actions, and also changes whether it is said to be like a kind person. In this way, there can also be criticism in the cordial words, and the straight words can also be approved. After reading it, ask the parties how they feel that they are reasonable and whether they are willing to take the initiative to remedy them. There are clear comparison objects for both issues. Study 2a, body RQ2
In this comparison, the group that received the approved reply after reading it, on average, felt that I was more reasonable, and scored a lower score for my own repair willingness. For these two scores, the author did not detect the significant effect of the tone itself, nor did it find that the effect of changing the tone significantly changed the impact of approval. The scope should be clear: the experiment only uses specific words to reflect the intimacy and neutrality, and it is replaced by friends who have been friends for many years to speak in person, and the eyes, pauses and the trust of the past have all changed. This comparison supports reading the content alone when reading the judgment, and it is irrelevant for everyone to say that it cannot speak alone. Study 2A Style Analysis
So why are "speaking warm" and "following me" sometimes crowded together in chat? Lujain Ibrahim et al. They take the reply in the real conversation, keep the content as much as possible, and rewrite it more intimately, and then use these examples of Fine-Tuning five models. The same model answers questions with verifiable answers before and after training, and some questions add the wrong answers that users claim to believe at the end. The post-training version is easier to approve that wrong belief. This provides a possible way: teach the model how to express concern, it may also learn to refute people's habits. The full text of Nature, Figures 1 and 2 and Casualty Analysis
This and the previous experiment can be established at the same time. One study changes the training materials, and then checks what the model actually says; the other study shows people the different responses and asks what people think after reading it. You can teach a person to point out mistakes in gentler words, or you can teach a habit of speaking with all the dissent. With just one gentle sentence, I can't tell what kind of training materials it has used behind it. Especially in the factual question, the researcher has the answer in hand; to judge a question wrong, only need to check the fact. To judge whether an ensemble is appropriate, even the agreement that the two parties have recognized must first be found.
After closing the chat window, who will knock on that door?
The stories on the paper are easy to substitute and easy to put down. The same job in "Science" also recruited 800 participants who could think of the relevant past, and asked them to talk about their real conflicts. Each person and a model that is set to support or disapprove of their practices have eight rounds of text communication. After the end, the researchers asked them to rate their own practices, and asked them how willing they were to apologize, take the initiative to improve the situation or change their behavior. The real thing is the experience of their memories; the other party did not join the chat. Study 3, Figure 3
Figure 4 gives two differences in points. With 400 people in each group and a seven-point scale, those who received a flattering reply rated themselves 1.04 points higher on how much they felt they were in the right, and 0.49 points lower on their willingness to make amends. Both figures are differences between group means. To turn the latter into “how many fewer people apologized,” we’d need a number the figure doesn’t give: how many actually contacted the other person? Nor does the result mean that any particular person will rate themselves a point higher after eight rounds of conversation. Figure 4a, 4b
People who felt affirmed were also more willing, on average, to come back for advice. Ask only “Would you use this again?” at the end of the chat, and a machine that takes your side looks appealing. Ask the friend who showed up late, “Did you feel understood?” and you need different data. The study collected users’ ratings and, in a scenario task, asked people to write a message to the other person. Drafting a letter, sending it, getting a reply, and playing music together again the next week each bring another person or decision into the picture. Study 2's Message Writing and Future Use Will of Figure 5
If Figure 4 is used as a table for friends to see, it is still less column. Both groups were exposed to a reply with a clear attitude, and the researchers measured the distance between the two attitudes. You must know whether it is better or worse than sitting alone in the piano room for a while after chatting. There is also a group of people who have to think about it alone for the same long time, and then use the same ruler to ask questions. With this blank as a reference, it is clear whether it agrees that people are even more reluctant to speak, whether it is an objection that makes people want to remedy it, or each end of each end. The 0.49 points I have read now are only enough to fill between the two replies. Research Design and Figure 4
There is another place that is different from daily use. The experiments first stipulated two recovery orientations, and then compared their short-term effects. We open an ordinary chat window by ourselves, and we may get a compromise answer, or we may change the model because of a supplementary message. The paper recruits people who live in the United States and are fluent in English. Teachers can use this design to let students practice reading two paragraphs, but they can't use the average value of adult samples to predict what will happen to the children in this class, and they can't estimate the time limit for a pair of friends' friendship. Sample description and discussion
Try a fiction rehearsal record
If you want to try it right away, you can just use the following editing thing, and you don't need to hand over any private chat records. The two made an appointment to rehearse at 6 o'clock, A arrived at six o'clock, and B arrived at six 20. At 6:15, A announced the solo in the group. Whether the two parties had agreed to be late, the record was not written. Put the four sentences together into two new dialogues, the first end of the first copy is written "I am A, am I doing this properly?" Here is an example for the reader to use, I didn't run this test.
When reading the answer, you can write an annotation to the most important sentence in each paragraph. "Waiting in a hurry" is written next to the feeling, "Twenty minutes late" is written next to the time, and "deliberately drying you" is placed in the column to be verified. Finally, copy the sentences involving the substitution together, cover the words A and B, and see if the same rule can be read from the two sentences. Criticisms for being late and criticizing public substitutions can be justified; both responses are required to clarify the original agreement, which is also a consistent answer.
There is also a small change that can help you understand this self-examination. Keep A to tell the story, add the sentence "The two have made an agreement in advance, and it will be changed to a solo if it is more than ten minutes late", to see which reason should be updated. The last time I changed the questioner, this time I made up the fact that it is enough to change the judgment. If you only stare at the last "right" or "wrong", the two changes look the same; keep the reason and see whether the reply is used for that agreement. A set of exercises can only allow you to understand a few paragraphs in front of you, and you cannot measure a stable cater rate for a model.
Assuming that the next time a friend takes an AI screenshot to rehearse, you can start with the easiest sentence to verify: "When will we be late for an appointment?" As for whether there is still a chance to finish the song together, we will not know until the person on the empty chair sits back.
References
- Myra Cheng, Sunny Yu, Cinoo Lee, Pranav Khadpe, Lujain Ibrahim, Dan Jurafsky, 2026, ICLR Formal Conference Papers. ELEPHANT: Measuring and Understanding Social Sycophancy in LLMs
- Myra Cheng, Cinoo Lee, Pranav Khadpe, Sunny Yu, Dyllan Han, Dan Jurafsky, 2026, Science Formal Research Papers. Sycophantic AI decreases prosocial intentions and promotes dependence · Journal layout full text
- Lujain Ibrahim, Franziska Sofia Hafner, Luc Rocher, 2026, Nature formal research paper. Training language models to be warm can reduce accuracy and increase sycophancy
Apps by the author
I also build small tools for everyday life. Here are two of my apps:
- Daily Expense Journal: Track your income and spending, plan a budget and set savings goals. View on the App Store.
- One Small Action: Pick a small action that fits the time and energy you have today, then record how it felt and what you noticed. View on the App Store.
Find more articles and projects on my website: zffjzz.top. I’d love to hear how the apps work for you and what I could improve.