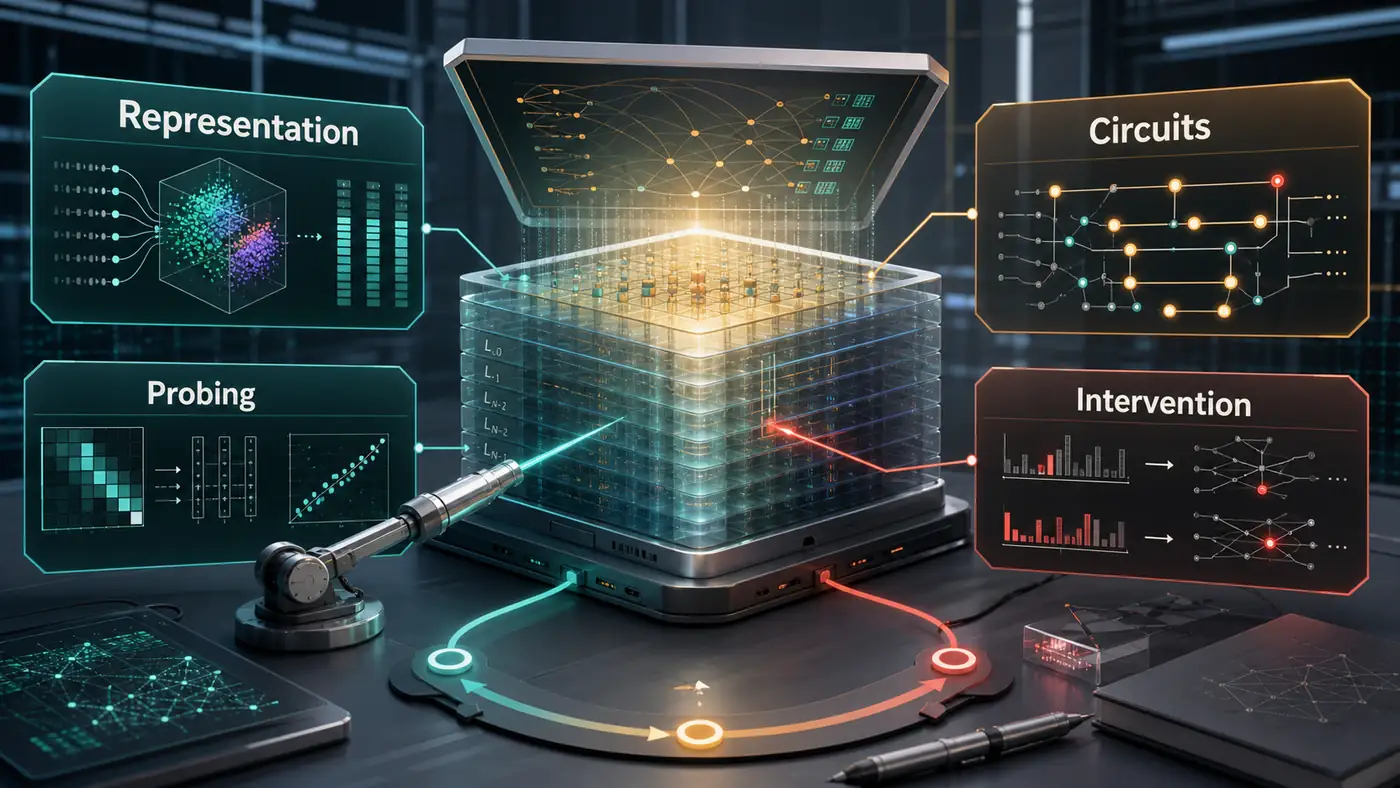
日期:2026-08-12
適合讀者:研究生、機制可解釋性入門研究者、有工程背景的 AI 讀者
檢索日期:2026-08-12
摘要
Interpretability,尤其是 mechanistic interpretability,已經從“給模型輸出配一張熱力圖”逐漸變成一套圍繞內部表示、因果乾預和可復現實驗組織起來的研究方法。讀這條線不能只問“這個神經元是什麼意思”,而要問:模型內部有哪些表徵單元?這些單元是否穩定?它們是否真的參與了輸出?如果我 patch、ablate 或 steer 它,模型行為是否按機制假設變化?
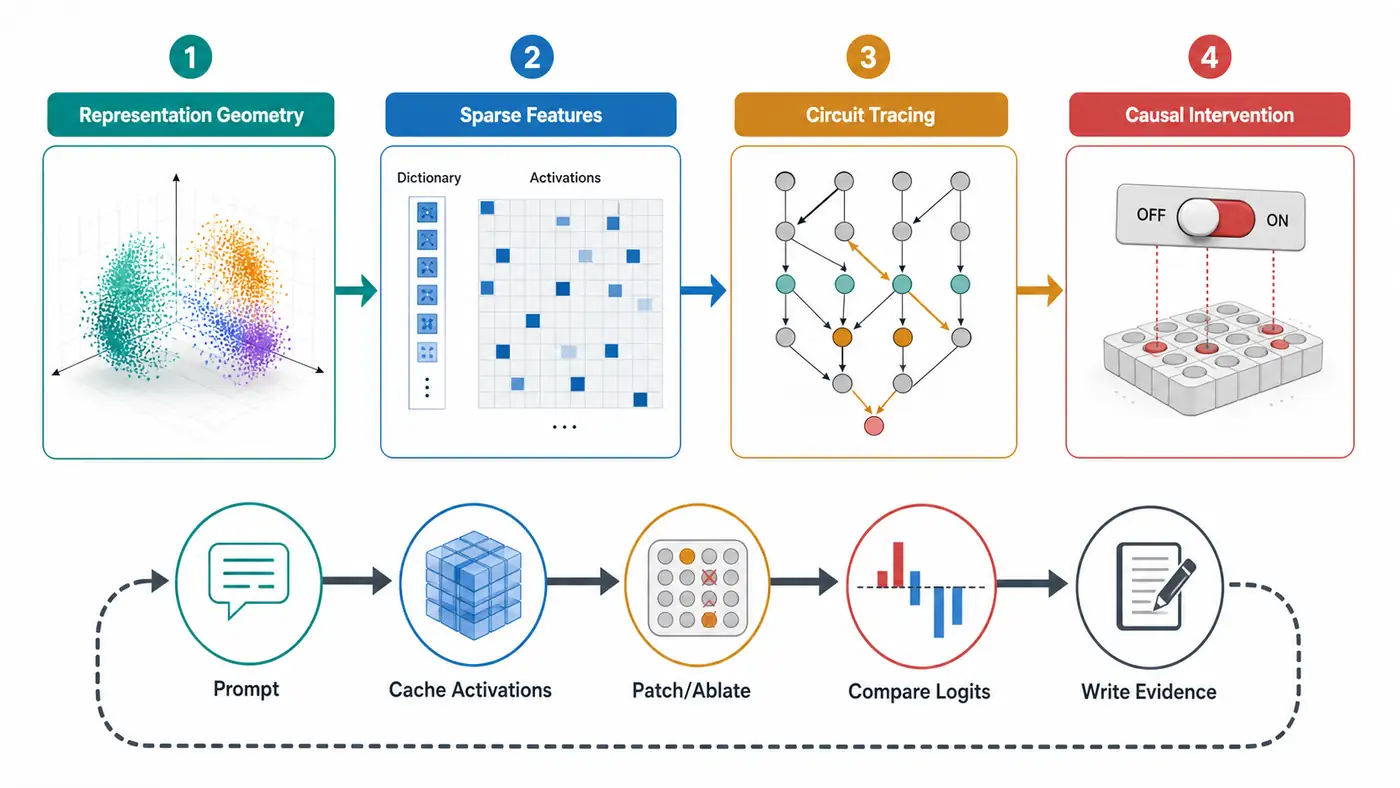
這篇文章給出一條適合科研訓練的論文精讀路線:先讀 representation 和 probing,理解“信息是否可讀出”;再讀 circuits,理解“組件如何組合成算法”;然後讀 sparse features / SAE,理解“為什麼單個神經元不夠、為什麼特徵也會失效”;最後讀 causal intervention、circuit tracing、Jacobian Lens 和 Natural Language Autoencoders,訓練自己把解釋從相關性證據推進到機制證據。
為什麼這個主題重要
大模型越強,外部行為越容易被提示詞、評測集和採樣設置掩蓋。一個模型答對了數學題,不等於它真的按可追蹤的中間步驟推理;一個模型拒絕有害請求,不等於內部沒有先識別、計劃或壓制某些內容;一個 SAE feature 看起來有清晰語義,也不等於它是模型實際使用的唯一因果變量。
2024 到 2026 年的進展讓這個方向變得更具體。OpenAI 發佈了 GPT-4 表徵的超大規模 sparse autoencoder 研究;Anthropic 從 Claude 3 Sonnet 的 monosemantic features 推進到 2025 年的 attribution graph / circuit tracing,再到 2026 年的 Jacobian Lens、J-space 和 Natural Language Autoencoders;Google DeepMind 的 Gemma Scope 與 Gemma Scope 2 把開放模型上的 SAE、transcoder 和交互式分析資源推給社區。與此同時,NeurIPS 2025 的 SAEBench、feature absorption、feature explanation falsification 等工作也提醒我們:解釋工具本身也需要 benchmark、反例和可證偽評價。
因此,interpretability 論文的讀法要比普通方法論文更苛刻。它不是“提出一個指標,跑幾個模型”,而是試圖回答“模型內部到底發生了什麼”。這類結論如果沒有 intervention、negative control、跨 prompt 復現和工具失效分析,很容易停留在漂亮可視化。
核心閱讀方法
讀 interpretability 論文時,建議把每篇文章拆成五個問題。
第一,解釋對象是什麼?是 token embedding、residual stream、attention head、MLP neuron、SAE latent、transcoder feature,還是 Jacobian lens 讀出的 verbalizable representation?對象不同,證據含義完全不同。一個 probe 讀出語法信息,只說明表示中含有可線性提取的信息;一個 ablation 改變輸出,才開始接近“這部分計算被模型使用”。
第二,解釋目標是什麼?論文是在解釋特定行為、特定數據分佈、某一類能力、某個安全相關傾向,還是模型的一般表徵空間?解釋 induction head 與解釋 Claude 的 evaluation awareness 不是同一層任務,不能用同一種證據標準。
第三,證據是相關性、可預測性,還是因果性?可視化激活最高樣本是相關性;linear probe 是可讀出性;activation patching、path patching、ablation、feature steering、model editing 才是更強的因果證據。最好的論文通常會把這些證據串起來,而不是隻展示一個漂亮案例。
第四,解釋工具有沒有自我校驗?SAE 要檢查 reconstruction loss、sparsity、feature consistency、dead features、feature splitting、absorption 和解釋可證偽性;circuit tracing 要檢查 replacement model 近似誤差;probe 要控制 probe 容量;Jacobian Lens 要記住它是平均線性化工具,不是完整讀取模型全部思維。
第五,復現邊界在哪裡?機制可解釋性很適合小模型訓練,但很容易在工程上失控。研究生更適合從 GPT-2 small、Pythia、Gemma 小模型、公開 SAE、TransformerLens、NNsight、Neuronpedia 和 circuit-tracer 之類工具開始,先復現一個小行為,再擴展到一個穩定問題。
代表論文路線圖
1. Representation 與 probing:先學會區分“可讀出”和“被使用”
入門可以從 probing literature 開始。Belinkov 的綜述很適合建立基本警覺:訓練一個分類器從 hidden states 預測語言屬性,不能直接證明模型在下游任務中使用了這個屬性。probe 太強會自己學任務,probe 太弱又可能漏掉真實信息。
這一階段要掌握三個動作:選層、選位置、選 probe 容量。讀論文時不要只看 probe accuracy,而要看 control task、selectivity、minimum description length、跨模型比較和干預驗證。一個好的 probing 實驗應該能告訴你“哪一層、哪個位置、用多複雜的讀出器,可以提取什麼信息”,但它通常還不能告訴你“這個信息是否驅動輸出”。
把 probing 讀紮實之後,再讀 logit lens、tuned lens 和 Jacobian Lens 會更清楚。它們本質上都在問:中間層表示能否被映射到人類可讀的詞表或語義空間。2026 年的 J-space 工作重要之處不只是提出一個 lens,而是把“可 verbalize 的表示”與 report、modulation、internal reasoning、flexible generalization、selectivity 等功能性質聯繫起來,並通過 intervention 檢查這些表示是否真的影響行為。
2. Circuits:從組件到算法
Transformer Circuits 線適合訓練“把網絡當程序拆”的能力。2021 年的 Mathematical Framework for Transformer Circuits 把 attention head 拆成 QK circuit 和 OV circuit,並用 path expansion 理解 attention-only transformer。2022 年的 induction heads 進一步把 in-context learning 的一部分現象拆成可定位的 attention head 組合:某些 head 會尋找上下文中曾出現過的模式,並複製後續 token。
讀 circuits 論文時,重點不是背術語,而是學它的證據鏈:先定義一個行為,比如 repeated token / indirect object identification / factual recall;再定位相關 head、MLP 或 feature;然後用 activation patching、path patching 或 ablation 證明這些組件對輸出有因果貢獻;最後檢查這個機制是否跨 prompt、跨模型或跨訓練階段穩定。
2025 年的 circuit tracing 把這個路線進一步規模化。它不再只盯著幾個 attention head,而是用 cross-layer transcoder 構造更可解釋的 replacement model,再把 prompt 上的計算展開成 attribution graph。閱讀時要注意一個關鍵限制:replacement model 是近似模型,它讓機制圖可讀,但也引入近似誤差。復現時必須記錄原模型與替代模型的輸出差異。
3. Sparse features 與 SAE:從“神經元語義”到“特徵空間”
單個神經元往往 polysemantic:同一個 neuron 可能參與多種概念,單個概念也可能分佈在多個 neuron 上。Anthropic 的 dictionary learning / monosemanticity 工作、OpenAI 的 GPT-4 concept extraction、DeepMind 的 Gated SAE 和 Gemma Scope,都圍繞一個核心假設展開:模型內部可能用稀疏特徵表示許多概念,SAE 可以把 dense activation 分解到更可解釋的 latent features。
這條線的閱讀順序可以是:先讀 toy model of superposition,理解為什麼“特徵多於維度”會導致重疊表示;再讀 Towards Monosemanticity,理解 dictionary learning 如何在小模型中找到可解釋 features;再讀 Scaling Monosemanticity 和 Extracting Concepts from GPT-4,理解規模化 SAE 的訓練和限制;最後讀 Gemma Scope / Gemma Scope 2,學習開放模型上的工具化資源。
但 SAE 不是解釋性的銀彈。2025 年的 SAEBench 提醒我們,重構誤差和稀疏度這類 proxy metric 未必等價於實際 interpretability utility;feature absorption 工作說明層級概念會讓看似單義的 feature 在該激活時不激活,被子特徵吸收;feature explanation falsification 進一步說明自動生成的 feature 解釋需要 close negative examples 來證偽。讀 SAE 論文時,必須同時讀“成功論文”和“失敗/評測論文”。
4. Causal intervention:解釋必須能被打斷、替換和反事實驗證
機制可解釋性最重要的訓練動作是 intervention。ROME 的 causal tracing 是經典例子:先通過 corruption + restoration 找到 factual association 對輸出最關鍵的中間狀態,再用 rank-one model editing 修改特定事實。它說明“定位”和“編輯”可以互相校驗:如果你說某個 MLP 中層存儲事實,就應該能通過有約束的編輯改變這個事實,並保持 specificity 與 generalization。
在 LLM 復現裡,最常見的 intervention 包括四類:activation patching,把 clean run 的某個 activation 放到 corrupted run;ablation,把某個 head、feature 或方向置零;steering,沿某個方向增強或抑制概念;path patching,只替換從某組件到某下游組件的路徑。每一種都要設計 negative control:隨機層、隨機 feature、無關 prompt、同義改寫和反向干預。
2025-2026 年的新工作把 intervention 用在更抽象的對象上。Circuit tracing 可以對 attribution graph 的 feature 做 intervention;J-space 工作可以在 verbalizable representation 上做 patch 或 ablation;Natural Language Autoencoders 則嘗試把 activation 經過自然語言瓶頸再重構,讓內部狀態以文本解釋形式可讀。它們都值得讀,但都要保持謹慎:越接近“讀出模型思想”的工具,越需要嚴肅區分工具輸出、模型輸出和真實因果機制。
方法與實驗對比表
| 方法線 | 代表工作 | 主要回答 | 最該檢查的證據 |
|---|---|---|---|
| Probing | probing classifiers, probing as inductive bias | 表示中是否含某類信息 | probe 容量、control task、跨層趨勢、是否有干預 |
| Transformer circuits | Mathematical Framework, Induction Heads | 組件如何組合成算法 | head/MLP 定位、path patching、跨 prompt 穩定性 |
| SAE / sparse features | Monosemanticity, GPT-4 SAE, Gemma Scope | dense activation 如何分解為 feature | reconstruction、sparsity、feature consistency、反例 |
| SAE evaluation | SAEBench, feature absorption, explanation falsification | 解釋工具何時失效 | proxy metric 是否有效、close negative、層級概念 |
| Causal tracing/editing | ROME, activation patching | 哪些狀態因果影響輸出 | corruption-restoration、specificity、generalization |
| Circuit tracing / CLT | Attribution graphs, circuit-tracer | prompt 級計算圖如何展開 | replacement model 誤差、邊權驗證、intervention |
| Lens / workspace | Jacobian Lens, J-space | 中間表示能否 verbalize 並參與推理 | lens 假設、層位置、patch/ablation、任務邊界 |
| Natural language bottleneck | Natural Language Autoencoders | activation 能否翻譯成文本解釋 | 重構質量、解釋忠實性、是否過度人類化 |
復現建議
第一階段,復現一個小行為。推薦從 GPT-2 small 或 Pythia 小模型開始,用 TransformerLens 緩存 residual stream、attention pattern 和 logits。任務可以選 repeated token、induction head、IOI 或 factual recall。目標不是做新 SOTA,而是寫清楚 clean prompt、corrupted prompt、目標 token、patch 位置和 logit difference。
第二階段,復現一個 SAE feature。可以使用 Neuronpedia、Gemma Scope 或公開 SAE 權重,選一個語義相對清晰的 feature,收集 top activating examples、near misses 和 close negatives。不要只展示正例;要記錄 feature 不該激活但激活、該激活但沒激活的樣本。
第三階段,復現一次 intervention。對某個 head、MLP activation、SAE feature 或 residual direction 做 ablation / steering,比較 logits、生成文本和任務正確率。每次 intervention 至少配三個對照:隨機同層位置、無關 feature、同義 prompt。
第四階段,寫 reproduction report。報告中至少包含:模型名和版本、代碼庫 commit、數據樣本、prompt 模板、隨機種子、hook 點、指標定義、所有失敗樣例、人工解釋規則和待人工核驗項。Interpretability 的復現報告尤其要寫“我不能證明什麼”,否則很容易把可視化誤讀成機制。
常見誤區
第一,把 attention map 當解釋。attention 權重可以提供線索,但不等於因果貢獻。至少要配合 value 路徑、logit attribution 或 patching。
第二,把 probe accuracy 當機制。probe 能讀出信息,不代表模型用這個信息完成任務。
第三,把 SAE feature 名稱當事實。很多 feature 解釋來自 top activating examples 或自動命名,必須用 negative examples、跨 seed 一致性和 intervention 檢查。
第四,只復現成功 prompt。機制解釋最怕 cherry-picking。應該主動構造同義、反義、無關、邊界和分佈外 prompt。
第五,過度擬人化。J-space、workspace、thoughts、Natural Language Autoencoders 等詞很容易讓讀者以為模型具有完整人類式思維。寫論文筆記時要把這些術語還原成工具定義和實驗操作,不要把哲學解釋當實驗證據。
適合研究生繼續做的選題
- SAE feature 解釋的 close negative 數據集:為一組公開 feature 系統構造“看起來相似但不應激活”的反例,評估自動解釋質量。
- 小模型 circuit 復現基準:把 induction head、IOI、factual recall、refusal toy task 做成統一 patching notebook。
- Probe 到 intervention 的證據升級:選擇一個 linguistic 或 reasoning 屬性,比較 probe、ablation、steering 三類證據是否一致。
- Gemma Scope / Neuronpedia feature 穩定性研究:比較不同層、不同 SAE 架構、不同 seed 的 feature 一致性與解釋質量。
- Jacobian Lens 與 logit lens 對比復現:在開放模型上比較兩種 lens 對中間層內容的可讀性和因果定位能力。
總結
Interpretability 論文的閱讀核心可以概括為一句話:先找可讀表示,再證明因果作用,最後承認工具邊界。Representation 和 probing 訓練我們不要把“可讀出”誤認為“被使用”;circuits 訓練我們把組件組合成算法;SAE 訓練我們從神經元升級到特徵空間,同時警惕特徵分裂、吸收和解釋幻覺;causal intervention 訓練我們用 patch、ablation、steering 和 editing 檢查機制假設。
對研究生來說,這個方向最好的入門方式不是直接解釋最大模型,而是在小模型上覆現一個可控機制,把每一步實驗日誌寫清楚。真正有價值的解釋不是漂亮圖,而是能被反事實打斷、能跨 prompt 復現、能說明自己何時失效的證據鏈。
參考資料
檢索日期:2026-08-12。以下優先列出論文、官方項目頁、會議頁面和一手資料;模型版本、工具 API、開源權重、交互式平臺內容和 benchmark 結果可能變化,復現前請再次核對。
- Elhage et al., “A Mathematical Framework for Transformer Circuits”, Transformer Circuits Thread, 2021. https://transformer-circuits.pub/2021/framework/index.html
- Olsson et al., “In-context Learning and Induction Heads”, Transformer Circuits Thread, 2022. https://transformer-circuits.pub/2022/in-context-learning-and-induction-heads/
- Belinkov, “Probing Classifiers: Promises, Shortcomings, and Advances”, Computational Linguistics, 2022. https://aclanthology.org/2022.cl-1.7/
- Meng et al., “Locating and Editing Factual Associations in GPT”, NeurIPS 2022 / ROME project page. https://rome.baulab.info/
- Bricken et al., “Towards Monosemanticity: Decomposing Language Models With Dictionary Learning”, Transformer Circuits / Anthropic, 2023. https://www.anthropic.com/research/towards-monosemanticity-decomposing-language-models-with-dictionary-learning
- Templeton et al., “Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet”, Anthropic, 2024. https://www.anthropic.com/research/mapping-mind-language-model
- Wu et al., “Extracting Concepts from GPT-4”, OpenAI, 2024. https://openai.com/index/extracting-concepts-from-gpt-4/
- Rajamanoharan et al., “Improving Dictionary Learning with Gated Sparse Autoencoders”, Google DeepMind / arXiv, 2024. https://deepmind.google/research/publications/88147/
- Lieberum et al., “Gemma Scope: Open Sparse Autoencoders Everywhere All At Once on Gemma 2”, 2024. https://deepmind.google/models/gemma/gemma-scope/
- Google DeepMind, “Gemma Scope 2: helping the AI safety community deepen understanding of complex language model behavior”, 2025. https://deepmind.google/blog/gemma-scope-2-helping-the-ai-safety-community-deepen-understanding-of-complex-language-model-behavior/
- Ameisen et al., “Circuit Tracing: Revealing Computational Graphs in Language Models”, Transformer Circuits Thread, 2025. https://transformer-circuits.pub/2025/attribution-graphs/methods.html
- Marks et al., “Sparse Feature Circuits: Discovering and Editing Interpretable Causal Graphs in Language Models”, ICLR 2025. https://proceedings.iclr.cc/paper_files/paper/2025/hash/3ba4d47a83e498c2b1a0868cba20f6de-Abstract-Conference.html
- Karvonen et al., “SAEBench: A Comprehensive Benchmark for Sparse Autoencoders in Language Model Interpretability”, arXiv, 2025. https://arxiv.org/abs/2503.09532
- Chanin et al., “A is for Absorption: Studying Feature Splitting and Absorption in Sparse Autoencoders”, NeurIPS 2025. https://proceedings.neurips.cc/paper_files/paper/2025/hash/764ff7477b8e24dbe01531f6791e8bdf-Abstract-Conference.html
- Ma et al., “Revising and Falsifying Sparse Autoencoder Feature Explanations”, NeurIPS 2025. https://proceedings.neurips.cc/paper_files/paper/2025/hash/5b6ce2529a79862a2d8ac57ac0e01d90-Abstract-Conference.html
- Gurnee et al., “Verbalizable Representations Form a Global Workspace in Language Models”, Transformer Circuits Thread, 2026. https://transformer-circuits.pub/2026/workspace/
- Anthropic, “A global workspace in language models”, 2026. https://www.anthropic.com/research/global-workspace
- Lindsey et al., “Natural Language Autoencoders Produce Unsupervised Explanations of LLM Activations”, Transformer Circuits Thread, 2026. https://transformer-circuits.pub/2026/nla/index.html
- TransformerLens official repository. https://github.com/TransformerLensOrg/TransformerLens
- NNsight official documentation. https://nnsight.net/index.html
- Neuronpedia official platform and documentation. https://www.neuronpedia.org/
- Anthropic circuit-tracer package. https://pypi.org/project/circuit-tracer/