Date: 2026-06-22
Suitable for readers: Enterprise knowledge base Q&A, customer service assistant, internal compliance assistant, research assistant or engineer, product leader and technical leader of a high-risk Agent.
Abstract
The previous article talked about mixed retrieval and reranking: how to combine keyword search, vector search, fusion sorting and reranker into a sortable closed loop that can be evaluated.
But even if the retrieval link is doing well, RAG will still encounter a more critical problem: When should you not answer directly?
Many systems regard "abstent" as the last sentence in Prompt:
如果不知道,请说不知道。
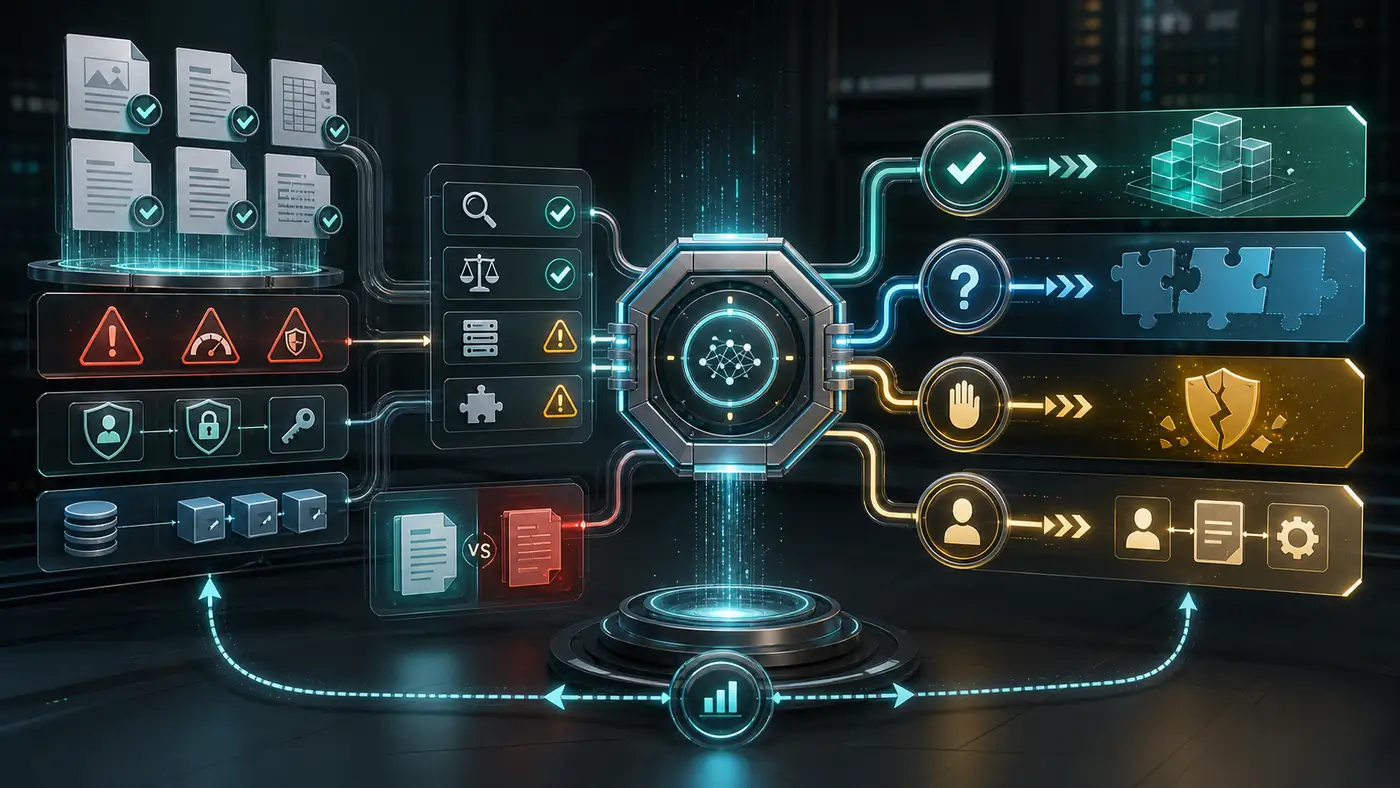
This sentence is useful, but not enough. What a production system really needs is a low Confidence decision-making layer. It reads search results, evidence support, evidence conflict, permissions, version, risk level, user intent integrity and tool status, and then chooses between four actions:
answer      证据足够,直接回答
clarify     信息缺失,先追问
abstain     证据不足或不允许回答,明确拒答
handoff     高风险或需要人工判断,转人工/转流程
This article gives a set of low-confidence and abstension strategies that can be implemented: how to define the confidence signal, how to distinguish between insufficient evidence and evidence conflict, ask what to ask, abstension How to write, which scenarios must be transferred to labor, how to carry decisions with structured output, how to evaluate the balance of "less wrong answers" and "not excessive abstent".
Contents
- 1. The goal is not less abstent, but less wrong answer
- 2. Four actions: answer, ask, abstention, transfer to labor
- 3. Low Confidence is not a fraction, but a set of signals
- 4. Evidence Confidence and Answer Confidence
- 5. Decision Matrix: From Signal to Action
- 6. When should you ask
- 7. When should abstension
- 8. When should I transfer to labor?
- 9. Bearing Decisions with Structured Outputs
- 10. A minimum Confidence policy engine
- 11. Answer, follow-up, abstent copy template
- 12. How to evaluate whether the abstention policy is valid
- 13. Online Observation and Accident Review
- 14. Proposals for Production Architecture
- 15. Common Mistakes
- 16. Landing road map
- 17. Pre-release self-check list
- 18. Summary
- References
1. The goal is not less abstent, but less wrong answer
After many teams go online, they will use "abstent rate" as a negative indicator: the less abstent, the better.
It's dangerous.
When a system answers on insufficient evidence, the result may sound fluent but be unreliable. The refusal rate may fall in the short term while trust erodes over time. A support agent might make a promise it cannot honor, a compliance system might misinterpret a rule, a research assistant might report a finding that does not exist, and an internal agent might take the wrong action.
The goal of producing a RAG is not "always giving the answer", but:
在证据足够时回答;
在信息缺失时追问;
在证据不足或不允许时拒答;
在高风险或需要判断时转人工。
These four actions should all be considered the path to success. Abstention is not a failure, a wrong answer is a failure. Questioning is not procrastination, it is making up for necessary conditions. Transferring labor is not insufficient, it is part of the risk boundary.
1.1 A typical accident
User asks:
企业客户提前取消年付套餐,是否可以退还剩余月份费用?
There are three pieces of evidence in the knowledge base:
证据 A:个人用户可以在取消后按剩余自然月退还未使用费用。
证据 B:企业客户合同以主协议为准,退款条款可能在补充协议中单独约定。
证据 C:2025 版企业客户政策已废止,2026 版政策未明确说明提前取消退款规则。
If the system answers:
可以,企业客户提前取消后可按剩余月份退款。
This is to misuse individual user rules to enterprise customers. There seems to be evidence, but the evidence does not support conclusions.
A more suitable action is:
我不能仅凭当前知识库确认企业客户提前取消年付套餐是否可退款。现有资料显示企业客户退款以主协议或补充协议为准,而当前检索结果没有找到该客户协议中的退款条款。请提供合同编号或协议条款;如果这是正式客户承诺,建议转财务/法务确认。
This answer is not dazzling, but it is credible.
2. Four actions: answer, ask, abstention, transfer to labor
The low Confidence layer of the RAG can first limit the output action to four categories.
| Action | applicable situation | User Experience Goals |
|---|---|---|
answer |
Sufficient evidence, no critical conflicts, and control of risks | give a concise answer and quote evidence |
clarify |
If you lack the necessary conditions, you can judge by adding a piece of information. | Ask a minimum necessary question |
abstain |
The knowledge base does not have enough evidence, or the system does not allow answers | Clear boundaries, do not fabricate |
handoff |
High risk, manual approval, external system or judgment responsibility is required | Give the problem to the correct process |
These four types of actions should be system contracts, not natural language styles.
It is recommended that before the end user reply is generated, Mr. becomes an internal decision object:
{
  "action": "clarify",
  "confidence": 0.58,
  "risk_level": "medium",
  "evidence_status": "partial",
  "missing_information": ["customer_type", "contract_version"],
  "reason": "The retrieved policy distinguishes personal and enterprise customers, but the user did not specify the contract type.",
  "allowed_to_answer": true
}
Only when action=answer Only then the system enters the normal answer generation. Other actions enter different response templates or workflows.
3. Low Confidence is not a fraction, but a set of signals
Many systems use only one retrieval score as the Confidence . For example, reranker score is greater than 0.8, and if it is less than 0.5, it is abstent.
This practice is too thick.
Low Confidence comes from at least six types of signals.
3.1 Retrieve signals
| Signal | Meaning |
|---|---|
top_score |
Highest Candidate Score |
score_margin |
The difference between first and second place |
recall_count |
Number of candidates over threshold |
direct_support_count |
The number of evidence judged directly supported by Reranker |
query_rewrite_drift |
Rewrite whether query is deviating from the original question |
source_diversity |
Whether multiple sources support the same conclusion |
The OpenAI Retrieval documentation is mentioned, score_threshold It is possible to limit the return of more relevant chunks, but the increase in threshold may also exclude useful content. This reminder is very important: the higher the threshold, the better, it must be adjusted in combination with Recall, the error rate and the abstention Rate.
3.2 Evidence signals
| Signal | Meaning |
|---|---|
support_type |
direct、partial、background、conflicting、irrelevant |
citation_coverage |
The key conclusion of the answer is whether there is a reference |
missing_conditions |
Is there a lack of applicable conditions |
version_status |
active、deprecated、draft、unknown |
freshness |
Whether the validity period is exceeded |
locator_quality |
Whether the reference can locate the page number, chapter, span |
Evidence is not "relevant text". Evidence must support a specific conclusion.
3.3 User Intent Signals
| Signal | Meaning |
|---|---|
intent_type |
Facts, Rules, Processes, Suggestions, Operations, Creation |
required_slots |
Determine whether the required conditions are complete |
ambiguity |
Are there multiple explanations for user issues? |
user_role |
Does user identity affect answers |
time_scope |
Whether the time range needs to be clear |
For example, "Can I get a refund?" This question must know the order type, user type, payment channel, policy version, and whether the deadline is exceeded. If a key condition is missing, you should ask or give a conditioned answer.
3.4 Risk Signals
| Risk | Example |
|---|---|
| legal risk | Contractual obligations, compensation, compliance interpretation |
| financial risk | Refund amount, tax treatment, invoice redemption |
| medical risk | Diagnosis, medication, test explanation |
| security risk | Dangerous operation, authority bypass |
| Privacy Risk | Personal data, customer information, internal data |
| operational risk | Will trigger real system state changes |
The same quality of evidence should have different actions under different risk levels. Low-risk FAQs can give conservative answers; high-risk compliance issues may require manual labor, even with some evidence.
3.5 Tool Status Signals
| Signal | Meaning |
|---|---|
retrieval_status |
Search is successful |
index_freshness |
Is the index just synced? |
tool_timeout |
Whether the tool timed out |
permission_check |
Permission check is successful |
source_availability |
Is the original text openable? |
Tool failures cannot be disguised as knowledge does not exist. Retrieving timeouts, indexes not synchronized, and permission services have failed, and should be degraded explicitly instead of allowing the model to play freely.
3.6 Answer consistency signal
| Signal | Meaning |
|---|---|
self_check_passed |
Can the answer be mapped to evidence sentence by sentence? |
claim_count |
How many independent statements are in the answer |
unsupported_claim_count |
How many statements have no evidence |
conflict_count |
How much evidence conflicts with each other |
policy_violation |
Whether to trigger internal rules |
After the final answer is generated, there is also an evidence alignment check. Many wrong answers are not retrieval failures, but the model said one more word without evidence during the generation stage.
4. Evidence Confidence and Answer Confidence
It is recommended to split the Confidence into two layers:
Evidence Confidence:检索到的证据是否足够支持问题?
Answer Confidence:生成出来的答案是否忠实于证据?
These two scores cannot be mixed together.
4.1 Evidence Confidence
Evidence Confidence focuses on the retrieval and Evidence itself.
Consider:
- whether there is direct support for evidence;
- number of direct evidence;
- Whether the evidence is from the Active version;
- whether there is evidence of conflict;
- lack of key conditions;
- Whether the reference positioning is verifiable;
- Whether the evidence covers all sub-questions;
- Whether the search tool is successful.
4.2 Answer Confidence
Answer Confidence focuses on generating results.
Consider:
- answers whether each key statement has evidence;
- whether the partial evidence is written as a definite conclusion;
- whether the applicable conditions are ignored;
- Whether to write the old version as the current rule;
- whether the facts are added to the reference;
- Whether to comply with the abstention / transfer strategy;
- Whether to express uncertainty clearly.
Many teams only do the first layer, which leads to the retrieval evidence that it is partial, but the answer is written as direct. When it's actually online, both layers should be done.
5. Decision Matrix: From Signal to Action
Below is a practical action matrix.
| Condition | Recommended actions | Example |
|---|---|---|
| There is Direct Evidence, no conflict, low risk/medium | answer | Policy FAQ, Process Description |
| There is Direct Evidence, but the risk is high | answer with cause or handoff | contract, finance, medical |
| Partial Evidence only, missing key slots | clarify | Missing order type, time, version |
| Only background evidence | abstain or clarify | Find the background material but no rules |
| evidence conflicting | abstain or handoff | Two Active Documentation Conflicts |
| evidence deprecated | abstain, prompt version problem | Only hit expired policy |
| retrieval failed | abstain with system limitation | Retrieval service timeout |
| permission unknown | abstain | Permission service failed |
| user asks for action requiring approval | handoff | Refund, delete data, change contract |
| safety/compliance policy triggered | abstain or handoff | Generated requests are not allowed |
Instead of hiding in Prompt, the matrix can be turned into explicit policy.
5.1 A simplified decision tree
1. 请求是否允许处理?
   no  -> abstain
2. 权限和工具状态是否正常?
   no  -> abstain or retry
3. 是否缺少必要条件?
   yes -> clarify
4. 是否有直接证据支持?
   no  -> abstain
5. 是否存在关键冲突?
   yes -> handoff or abstain
6. 风险是否高到需要人工判断?
   yes -> handoff
7. 否则 answer
Pay attention to the order. Don't ask the model "how sure you are", and then check the permissions. Permissions, policies, and security boundaries should be judged first.
6. When should you ask
The inquiry is applicable to the situation that "make up one or a few information can be answered".
6.1 Good Scenarios for Inquiry
| Scenes | Why ask |
|---|---|
| Missing user type | Individual and corporate rules are different |
| Lack of product line | Different product policies are different |
| Missing time range | Policy versions vary by date |
| missing area | Different regulations or operating rules |
| Missing order status | To be paid, shipped, completed different |
| missing target | The user asks "how to deal with it" but doesn't say the target |
For example:
用户:这个订单可以退款吗?
系统:我需要确认两个信息才能判断:这是个人订单还是企业合同订单?订单当前是未发货、已发货还是已完成?
6.2 Asking questions should be less and accurate
The most common question is to ask too much at one time.
Bad example:
请提供订单号、用户类型、支付方式、订单状态、购买时间、所在地区、合同版本、产品线和退款原因。
Good example:
请先确认订单类型:这是个人订单还是企业合同订单?这会决定适用哪套退款规则。
The goal of asking questions is not to collect all information, but to obtain the most critical gap in current decision-making.
6.3 You can give a conditional answer, but you need to standardize the boundary
In some cases, you can give a conditional framework before inquiring:
如果这是个人订单,当前政策通常按剩余未使用月份计算退款;如果这是企业合同订单,需要以主协议或补充协议为准。请确认订单类型,我再给你对应规则。
This answer is more helpful than direct abstention and is safer than unconditional answers.
7. When should abstension
abstention works in the case where the current system should not answer or cannot be reliably answered.
7.1 Insufficient evidence
If there is no direct evidence for the search results, the system should make it clear that:
我没有在当前知识库中找到能支持这个结论的资料。
Don't write:
根据常识,可能是……
The value of the RAG system lies in the answer based on evidence. When there is no evidence, common sense speculation should be clearly downgraded.
7.2 Conflict of evidence
If two active sources conflict, do not choose one without authorization.
我找到了两条互相冲突的现行资料:A 文档说企业客户需按主协议处理,B 文档说可按剩余月份退款。当前无法判断哪条优先级更高,建议由财务或法务确认。
The key here is to expose the conflict, not to hide it.
7.3 version is uncertain
When only an expired document is hit, it cannot be regarded as the current rule.
我只找到了 2025 版已废止政策,没有找到当前有效版本。不能据此确认现在的处理规则。
7.4 Insufficient permissions or privacy risks
When the user has no access to the material, abstention should not leak the material existence and content.
我无法访问或确认你有权限查看相关资料,因此不能回答这个问题。
Don't say:
有一份内部法务备忘录提到了这个条款,但你无权查看。
7.5 Safety or compliance is not allowed
This kind of abstention is not low confidence, but explicitly not allowed. The tone should be concise and do not provide bypass paths.
8. When should I transfer to labor?
Transfer labor is applicable to the situation that "the system can find problems, but should not complete judgment or commitment alone".
8.1 High-risk business commitments
For example:
- Whether to promise customer refunds;
- whether to cancel the contract responsibility;
- whether to give legal explanation;
- whether to diagnose medical examinations;
- Whether to approve high compensation;
- Whether to modify user permissions;
- Whether to delete or export sensitive data.
Even with evidence, these scenarios may require manual approval.
8.2 Conflict of evidence but business must continue
Some problems can't just be abstent, because the user needs process progression. The system should be transferred to labor and carry the evidence package.
{
  "handoff_to": "finance_ops",
  "reason": "conflicting_active_policy",
  "evidence": [
    {"source_id": "enterprise_refund_policy_2026", "claim": "enterprise refunds follow master agreement"},
    {"source_id": "billing_faq_2026", "claim": "annual plans may refund remaining months"}
  ],
  "user_question": "企业客户提前取消年付套餐是否可退费?"
}
When you take over manually, you hate to look at the dialogue from the beginning. The system should package the problems, candidate evidence, conflict points, user missing information and have made judgments.
8.3 HITL is not the bottom line, but the product process
OpenAI's application development data also emphasizes that Guardrails and evals are the basis of production-grade trusted systems, and high-risk or low-confidence outputs should be introduced into Human-in-the-Loop. The focus here is not "people to repair the model", but to make the product have a clear boundary of responsibility.
9. Bearing Decisions with Structured Outputs
Low Confidence policies should not rely solely on the model to generate a natural language. It is recommended to make a structured decision, and then convert it from a template or controlled generator to a user reply.
The OpenAI Structured Outputs document emphasizes that Structured output can help applications get JSON schema-compliant results, and safe abstent can be programmatically detected. This ability is very suitable for internal decisions that carry RAGs.
9.1 Decision Schema
{
  "type": "object",
  "additionalProperties": false,
  "required": [
    "action",
    "confidence",
    "risk_level",
    "evidence_status",
    "missing_information",
    "conflicts",
    "answer_policy",
    "user_message"
  ],
  "properties": {
    "action": {
      "type": "string",
      "enum": ["answer", "clarify", "abstain", "handoff"]
    },
    "confidence": {
      "type": "number",
      "minimum": 0,
      "maximum": 1
    },
    "risk_level": {
      "type": "string",
      "enum": ["low", "medium", "high", "critical"]
    },
    "evidence_status": {
      "type": "string",
      "enum": ["direct", "partial", "background", "conflicting", "missing"]
    },
    "missing_information": {
      "type": "array",
      "items": {"type": "string"}
    },
    "conflicts": {
      "type": "array",
      "items": {
        "type": "object",
        "required": ["source_a", "source_b", "issue"],
        "properties": {
          "source_a": {"type": "string"},
          "source_b": {"type": "string"},
          "issue": {"type": "string"}
        }
      }
    },
    "answer_policy": {
      "type": "object",
      "required": ["can_answer", "must_cite", "must_handoff"],
      "properties": {
        "can_answer": {"type": "boolean"},
        "must_cite": {"type": "boolean"},
        "must_handoff": {"type": "boolean"}
      }
    },
    "user_message": {
      "type": "string"
    }
  }
}
9.2 Why Structured
Structured decisions have several benefits:
- Products can count the action distribution;
- Projects can go through different processes by action;
- The evaluation can directly judge whether the action is correct;
- High-risk scenarios can force handoff;
- The UI can display the questioning or transfer to the artificial state;
- The log can review each abstension reason;
- Different model versions can be compared with A/B.
Natural language answers are for users to see, and structured decisions are for the system. Don't mix the two.
10. A minimum Confidence policy engine
Below is a simplified version of the strategy engine. In the real system, the score comes from Retriever, reranker, Evidence validator, risk classifier and permission services.
from dataclasses import dataclass
from typing import List, Literal


Action = Literal["answer", "clarify", "abstain", "handoff"]
EvidenceStatus = Literal["direct", "partial", "background", "conflicting", "missing"]
RiskLevel = Literal["low", "medium", "high", "critical"]


@dataclass
class RagSignals:
    evidence_status: EvidenceStatus
    top_score: float
    direct_support_count: int
    conflict_count: int
    missing_slots: List[str]
    risk_level: RiskLevel
    retrieval_ok: bool
    permission_ok: bool
    active_version_only: bool
    unsupported_claim_count: int


@dataclass
class Decision:
    action: Action
    confidence: float
    reason: str
    missing_information: List[str]


def decide(signals: RagSignals) -> Decision:
    if not signals.permission_ok:
        return Decision(
            action="abstain",
            confidence=0.0,
            reason="Permission check failed or user lacks access.",
            missing_information=[],
        )

    if not signals.retrieval_ok:
        return Decision(
            action="abstain",
            confidence=0.1,
            reason="Retrieval failed, so absence of evidence cannot be trusted.",
            missing_information=[],
        )

    if signals.risk_level == "critical":
        return Decision(
            action="handoff",
            confidence=0.4,
            reason="Critical-risk request requires human review.",
            missing_information=signals.missing_slots,
        )

    if signals.missing_slots:
        return Decision(
            action="clarify",
            confidence=0.5,
            reason="Required information is missing.",
            missing_information=signals.missing_slots[:2],
        )

    if signals.conflict_count > 0 or signals.evidence_status == "conflicting":
        action: Action = "handoff" if signals.risk_level in ["high", "critical"] else "abstain"
        return Decision(
            action=action,
            confidence=0.35,
            reason="Retrieved evidence contains unresolved conflicts.",
            missing_information=[],
        )

    if not signals.active_version_only:
        return Decision(
            action="abstain",
            confidence=0.3,
            reason="Only deprecated or uncertain-version evidence was found.",
            missing_information=[],
        )

    if signals.evidence_status != "direct" or signals.direct_support_count == 0:
        return Decision(
            action="abstain",
            confidence=min(signals.top_score, 0.45),
            reason="No direct evidence supports the requested conclusion.",
            missing_information=[],
        )

    if signals.unsupported_claim_count > 0:
        return Decision(
            action="abstain",
            confidence=0.55,
            reason="Draft answer contains claims not supported by retrieved evidence.",
            missing_information=[],
        )

    if signals.risk_level == "high" and signals.direct_support_count < 2:
        return Decision(
            action="handoff",
            confidence=0.65,
            reason="High-risk answer needs stronger support or human approval.",
            missing_information=[],
        )

    return Decision(
        action="answer",
        confidence=max(signals.top_score, 0.75),
        reason="Direct active evidence supports the answer and no blocking risk was detected.",
        missing_information=[],
    )
This strategy engine has several features:
- Permissions and tool states precede the model Confidence ;
- Priority will be given first when there is no slot;
- Conflict of evidence is not forced to choose;
- The old version of evidence will not be regarded as the current rule;
- High-risk issues require stronger evidence or labor;
- The generated unsupported claims will block the output of the answer.
When you are actually online, you can configure these rules and set different thresholds according to the business line.
11. Answer, follow-up, abstent copy template
The strategy layer determines the action, and the copywriting layer determines the user experience.
11.1 answer Template
When the evidence is sufficient:
可以。根据《退款政策 2026-03》第 4.2 节,命中 E7782 的订单必须进入人工审核,不得自动退款。审核完成后,退款通常在 1-5 个工作日内退回原支付渠道。
Key points:
- answer the conclusion first;
- clear conditions;
- reference source;
- Do not expand the content outside the evidence.
11.2 clarify Template
Suitable for lack of necessary conditions:
我需要先确认一个条件:这是个人订单还是企业合同订单?当前资料显示两类订单适用的退款规则不同。
Key points:
- only ask the most critical gap;
- explain why this information is needed;
- Do not push users back to complex forms.
11.3 abstain Template
Suitable for insufficient evidence:
我不能根据当前知识库确认这个结论。检索结果只包含个人订单退款规则,没有找到企业合同订单提前取消时的退款条款。
Key points:
- what is not clearly answered;
- explain the reason;
- do not fabricate alternative answers;
- If possible, give the next step.
11.4 handoff Template
Suitable for high risk or manual approval:
这个问题涉及企业合同退款承诺,需要财务或法务确认。我已整理出相关资料:当前政策说明企业客户以主协议为准,但知识库没有找到该客户合同的具体退款条款。建议转财务运营处理。
Key points:
- Explain why you are transferred to labor;
- bring the evidence found;
- Do not allow users to repeatedly provide information;
- Give a clear flow object.
12. How to evaluate whether the abstention policy is valid
Low Confidence policies must be evaluated, otherwise it is easy to go to two extremes:
- Overconfidence: wrong answers are small but serious;
- Excessive conservative: a large number of answerable questions are abstention.
12.1 Sample Set Design
The evaluation set contains at least these buckets:
| sample bucket | desired action |
|---|---|
| General question of sufficient evidence | answer |
| Missing Critical Conditions | clarify |
| Questions with no answer to the knowledge base | abstain |
| Problems with only background evidence | abstain |
| The issue of conflicting evidence | abstain or handoff |
| Only the old version of the evidence | abstain |
| High risk but some evidence | handoff |
| Insufficient permissions | abstain |
| Retrieve tool failed simulation | abstain with system limitation |
| User is malicious or does not allow requests | abstain |
12.2 Indicators
| Metric | Meaning |
|---|---|
| Action Accuracy | Whether the action is right |
| Unsafe Answer Rate | Proportion of answering abstent / transferring to labor but answering |
| Over-Abstain Rate | The ratio of answer to Abstention |
| Clarification Precision | Ask if there is a key gap |
| Handoff Precision | Is it really necessary to transfer labor? |
| Evidence Support Rate | Is there evidence for the key statement in answer |
| Conflict Detection Rate | Whether conflict evidence is identified |
| Version Safety Rate | Is the old version properly intercepted? |
| User Resolution Rate | Whether the user finally solves the problem |
12.3 Cost Functions
The cost of different errors is different.
| Error | Cost |
|---|---|
| should absention but answer | Highest |
| Should be transferred to labor but answered | Highest |
| Answer the question | High |
| Absention should be answered | In |
| answer but ask | Low medium |
| Should Abstention but switch to manual | In |
Don't just average Accuracy when reviewing. In a medical, legal or financial system, the cost of a small number of wrong answers may be much higher than a large number of conservative abstents.
13. Online Observation and Accident Review
The low Confidence decision signal should be recorded for each RAG request.
Recommended log fields:
{
  "request_id": "req_20260622_001",
  "query": "企业客户提前取消年付套餐可以退款吗?",
  "action": "handoff",
  "confidence": 0.62,
  "risk_level": "high",
  "evidence_status": "partial",
  "top_score": 0.81,
  "direct_support_count": 0,
  "conflict_count": 0,
  "missing_slots": ["contract_id"],
  "retrieval_strategy": "hybrid_rrf_rerank_v3",
  "answer_policy_version": "confidence_policy_v2",
  "handoff_team": "finance_ops",
  "created_at": "2026-06-22T12:40:32+08:00"
}
There are five questions to answer when reviewing online:
- Does the correct evidence enter the candidate pool?
- Does Reranker put the right evidence in the front?
- Does the decision-making level correctly identify the status of evidence?
- Is the generation of answers faithful to evidence?
- Does the user feedback indicate that the action selection is inappropriate?
Without these logs, the team can only rely on guessing.
14. Proposals for Production Architecture
The low Confidence layer can be placed between retrieval and generation, or can be checked again after generation.
User Query
  -> Input Guardrails
  -> Query Analyzer
  -> Retrieval and Reranking
  -> Evidence Classifier
  -> Risk Classifier
  -> Confidence Policy Engine
      -> answer  -> Grounded Generation -> Claim Check -> User
      -> clarify -> Clarification Template -> User
      -> abstain -> Refusal Template -> User
      -> handoff -> Handoff Package -> Human Workflow
  -> Logging and Evals
14.1 Evidence Classifier
Divide the candidate evidence into:
directpartialbackgroundconflictingirrelevant
This step can be implemented with reranker, Rules, LLM Judge, or a combination.
14.2 Risk Classifier
Classify requests by business risk:
low: General knowledge Q&A;medium: affect user operations but do not generate commitments;high: Finance, legal affairs, medical care, security, privacy;critical: irreversible operation or major responsibility may arise.
The risk classifier does not need to be perfect, but it must be conservative.
14.3 Confidence Policy Engine
It is not recommended to give it to the generative model. The policy engine should consist of rules, thresholds, and auditable configurations. Models can provide evidence to understand and classify, but the ultimate action is best controlled by product policies.
14.4 Claim Check
even if action is answer, after generation, also check whether the key statement in the answer is supported by evidence. You can split the answer into CLAIMS, and then verify it one by one:
[
  {
    "claim": "命中 E7782 后不得自动退款",
    "support": "supported",
    "citation": "refund_policy_2026_03#sec_4.2"
  },
  {
    "claim": "审核通常需要 1-5 个工作日",
    "support": "supported",
    "citation": "refund_policy_2026_03#sec_4.2"
  }
]
If the unsupported claim appears, rewrite the answer or change it to abstain.
15. Common Mistakes
15.1 Misunderstanding 1: Rely on a Prompt to deal with Abstention
"If you don't know, say you don't know" is necessary but not sufficient. Systems require structured signals, action matrices, thresholds, logs, and reviews.
15.2 Misunderstanding 2: Equivalently a low score is to not answer
Low scores may be a question of retrieval strategy, or it may be a query that needs to be asked. You cannot simply use a low score abstention .
15.3 Misunderstanding 3: Equivalently high scores can be answered
High score candidates may be just semantically similar and do not necessarily support conclusions. Also look at Direct Support, conflicts, versions, permissions, and risks.
15.4 Myth 4: Abstention copy is too vague
Bad Abstention :
抱歉,我无法回答。
good abstent :
我不能根据当前知识库确认这个结论,因为检索结果没有找到企业合同提前取消的退款条款。
15.5 Myth 5: Inquiries become forms
The minimum necessary information should be asked, not to throw all the fields to the user.
15.6 Misunderstanding 6: Transferring to labor without context
Transfer workers without evidence package increase labor costs. Handoff must carry user issues, system judgments, candidate evidence, missing information and points of conflict.
15.7 Myth 7: Just look at abstention Rate
abstention rate low may be a good thing, or it may be the system in Hu. To look at Unsafe Answer Rate, Over-Abstain Rate, Clarification Precision and User Resolution Rate at the same time.
16. Landing road map
Week 1: Define Actions and Logs
- Fix the output action to answer, clarify, abstain, handoff;
- Record Action, Confidence, Risk, Evidence Status for each request;
- Sort out high-risk business scenarios;
- Define the first version of abstention and the question template.
Week 2: Establishing the Evidence Classification
- Divide the search candidates into Direct, Partial, Background, Conflicting, and Irrelevant;
- Access version and permission status;
- Record the Direct Support Count and Conflict count;
- Let the final answer refer to Direct Evidence.
Week 3: Implementing the Strategy Engine
- Write the decision matrix as a configurable rule;
- go Clarify when missing slot;
- Conflict, high risk, critical request to go to handoff;
- Retrieve failure, permission failure, old version of the evidence go to Abstain;
- Add a version number to the policy configuration.
Week 4: Build an evaluation set
- Manually construct each type of action sample;
- Join the online failure sample;
- Evaluation Action Accuracy, Unsafe Answer Rate, Over-Abstain Rate;
- Barrels by risk level and query type.
Week 5: Access to the manual process
- design handoff package;
- Docking work orders, customer service, legal or financial processes;
- Record the final result of the labor process;
- Manually re-reflow the evaluation set.
17. Pre-release self-check list
action contract
- The system explicitly supports answer, clarify, abstain, handoff;
- Each action has a trigger condition;
- Each action has a user-understood copy;
- Action selection writes to structured logs;
- The policy version can be traced and rolled back.
Evidence
- Candidate evidence has the Direct/Partial/Background/Conflicting/Irrelevant classification;
- The key statement of the answer must have a reference;
- The old version of the evidence will not be regarded as the current rule;
- Conflict of evidence prevents direct answers;
- Failure of retrieval is not considered to exist as knowledge does not exist.
Examine minutely
- Priority is given when critical slots are missing;
- No more than 1-2 key questions are asked at a time;
- Inquire why this information is needed;
- abstention can be used to give conditionalization frameworks;
- The context can continue to be used after the inquiry.
Abstention
- abstention specifies the specific boundary;
- Do not disclose information that users do not have the right to know;
- Do not provide unsupported guesses after abstention;
- Do not confuse safe abstent with low confidence abstent;
- abstention sample enters the evaluation set.
Transfer to labor
- High-risk and Critical scenarios have handoff rules;
- handoff package contains evidence, gaps and points of conflict;
- Users do not need to repeatedly provide known information;
- The results of manual processing can be written back;
- The manual revision will be followed up with the follow-up evaluation.
Evaluation
- There are four types of gold sets answer/clarify/abstain/handoff;
- Statistics unsafe answer rate;
- Statistics over-abstain rate;
- Buckets by risk level;
- Divide the bucket by query type;
- There are A/B or playback reviews before the strategy goes live.
18. Summary
The credibility of the RAG depends not only on retrieval and generation, but also on whether the system knows its own boundaries.
A low-confidence policy needs decision rules that the system can act on. Use evidence quality, missing details, conflicting sources, permissions, versions, tool status, and risk level to select the next action. Answer when the evidence supports an answer. Ask a follow-up when a necessary detail is missing, abstain when evidence is insufficient, and hand high-risk cases to a person.
A practical principle is:
不要让生成模型独自决定是否该回答。
让证据、风险和产品策略共同决定。
Doing this makes the RAG system just not appear smart when it's right, but still reliable when it's uncertain.
Next article can continue to write: How to do RAG's answer generation and context packaging: how to turn evidence into a reliable answer.
References
- OpenAI Developers, Retrieval guide: Ranking, checked on 2026-06-22.
- OpenAI Developers, File search guide, checked on 2026-06-22.
- OpenAI Developers, Structured model outputs, checked on 2026-06-22.
- OpenAI Developers, AI app development: Building guardrails, checked on 2026-06-22.
- OpenAI Cookbook, Practical Guide for Model Selection for Real-World Use Cases, checked on 2026-06-22.