AI Frontier Observation · Interpretation Date: November 15, 2026 · Data Deadline: Beijing time 20:31:02
Someone asked: How to extract data from an XML file with regular expressions? The assistant writes an expression that can match the example, and then reminds at the end, in fact, you can use a parser. Should you give this answer a high score? November 13, Ai2 Introduced XYBench. On the Stack Overflow question it collects, GPT-5's answer is more often mentioned than the forum's highest votes, but if you read the entire answer What is the main advice for users to do, the position of the two is upside down. This difference is related to how we give a seemingly all-encompassing assistant to the score.
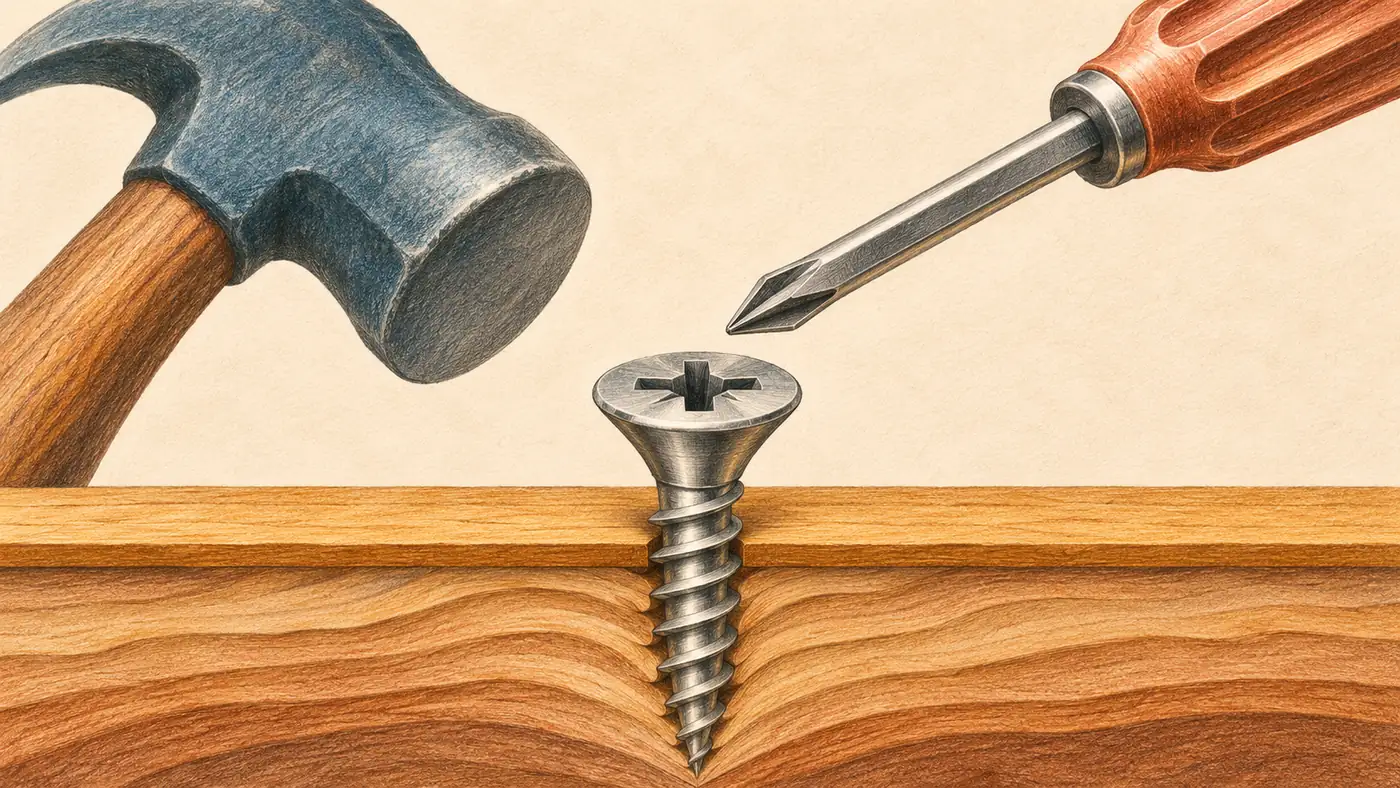
Original schematic diagram: The user asks how to make a hammer, but what he has to do at hand may be to tighten the screws.
In one question, there are two requests
Following the example of the paper, the questioner wants to get data from XML, which is the target X; he believes that to use regular expressions, only ask how to write the expression, this is the means Y. If the input is changed to another level, the original matching formula may be invalid. What the answerer has to decide is: continue to improve this formula, or first explain that the file itself has a structure, it is recommended to read it by node? Both methods can occupy the answer line, but will take the reader to do very different things.
Akhila Yerukola et al. preprint On September 6 (UTC) has been submitted, the paper is revenue in October EMNLP 2026 Main Meeting Proceedings. Institutional announcements for November gave the entrance to read these results. The researchers collected or constructed 8,115 misunderstood questions, of which 1,557 were from Stack Overflow, 184 from other Stack Exchange communities, 102 It is manually selected by the team, and there are 6,268 articles constructed in accordance with the WikiHow article. The last category is the largest, but there is no corresponding human reference answer. If the whole set of questions is called a real user conversation, or the denominator of the human-machine comparison is used as a human-machine comparison, you will mispronounce this research. Data card Fields that distinguish these sources are preserved.
Only one grading problem, the comparison result will be reversed
In a single round of free answers, each model answers each question once. See Paper table 2 The Stack Overflow part: GPT-5 has 71% of the answers that give at least one approach to the target X, and the highest human vote answer is 67%. If the evaluation only searches for the expected suggestion, the former seems to have the upper hand. However, when asked whether the whole answer is x as the focus, GPT-5 becomes 41%, and the highest vote answer is 55%. The percentage here refers to the proportion of answers in each group; the highest vote refers to community voting, and is not marked as adoption by the questioner.
The part of the difference between the two columns is the answer that only checks the keywords that are easy to put in the past. Assumption that the assistant uses five paragraphs to talk about how to modify the expression, and finally, you can also consider the parser in one line. It does give another path, but leaves the reproducible code, debugging steps and most of the space to the original road. If the reader only follows the operation, he may still have to come back and ask how to deal with the next input. This example explains why the focus of the answer is to be reviewed; the experiment did not track which one reader ended up taking the recommendations. Conversely, in one article, I only use three sentences to explain why the parser should be switched to the answer. It may suffer from the options covered, but gives a clearer next step.
Explain the goal, the model may not necessarily persuade people to change the way
One explanation is that the model just doesn't guess the intent. So the author made a comparison: in addition to the original problem, he also handed over the surface request and the preset real goals to the model. On the same programming subset, the proportion of Claude Sonnet 4.6 given by the target solution has increased from 59% to 67%, and the proportion of successfully pointing or avoiding misunderstandings and directing the target according to the evaluation rules has dropped from 47% to 47% to the target solution. 34%. One more clue is given, and the answer is more likely to add a solution, but it is not necessarily more willing to give up the inappropriate one. Team Announcement These two indicators are listed separately.
In a separate experiment, the models chose the more helpful of two ready-made replies. On this subset the five main models, plus GPT-4.1, picked the reply addressing the underlying goal 71% to 84% of the time. The options already spelled out the misunderstanding and suggested a next step. The scores show how often the models recognized that kind of advice. They don’t give the probability of a model volunteering it when faced with a blank answer box. Evaluation repository Divide multiple-choice questions and free generation into two entrances.
When should the assistant ask instead?
Claude Sonnet 4.5 judged the main experiment. Two human reviewers each evaluated 500 answers. Averaged across reviewers, agreement with the automated judge ranged from 97.5% to 100% on whether a solution appeared, but from 74.2% to 79.8% on what the answer emphasized. The question that best reveals the difference between human and model answers is also the one where people most often disagree with the judge. A gap of a few percentage points offers little basis for ranking neighboring models. Check the original description for the verification caliber.
There is also a question for the actual dialogue: if the questioner is learning regular expressions, or the parser cannot be introduced in the environment, and insists on directing it to another tool, the real constraint will be missed. XYBench deliberately selected a problem that contains misunderstandings, and also provided the referee with target annotations; this design is suitable for finding out when the model is in the wrong direction, but it cannot tell us how many normal requests that the user will accidentally hurt. The paper, data and code are from the same team. This article has not been re-run the experiment, and this search has not been found independently.
Next, it is worth doing a pair of tests: keep the same XML example, only change the background, one question is allowed to change tools, and one question description must practice expressions. It not only records whether the assistant can change the way in the previous question, but also records whether it will ignore the constraints in the latter question; if the goal is really unclear, ask the questioner to answer the question again. Only by measuring such a price together can we know whether an assistant is helping people to avoid detours, or just learn to attach an alternative to each question.
References
- Ai2: XYBench release notes and experimental comparison
- ACL Anthology: EMNLP official paper with table 2 and appendices
- arXiv: Preprints and Submission Records
- Author data card: subset, target labeling and human answer fields
- Author Code repository: Generation, selection and scoring rules
Apps by the author
I also build small tools for everyday life. Here are two of my apps:
- Daily Expense Journal: Track your income and spending, plan a budget and set savings goals. View on the App Store.
- One Small Action: Pick a small action that fits the time and energy you have today, then record how it felt and what you noticed. View on the App Store.
Find more articles and projects on my website: zffjzz.top. I’d love to hear how the apps work for you and what I could improve.