AI Frontier Observation: Characters, Breakthroughs and Evidence | Interpretation Date November 11, 2026 | Information as of 20:33:58 Beijing time
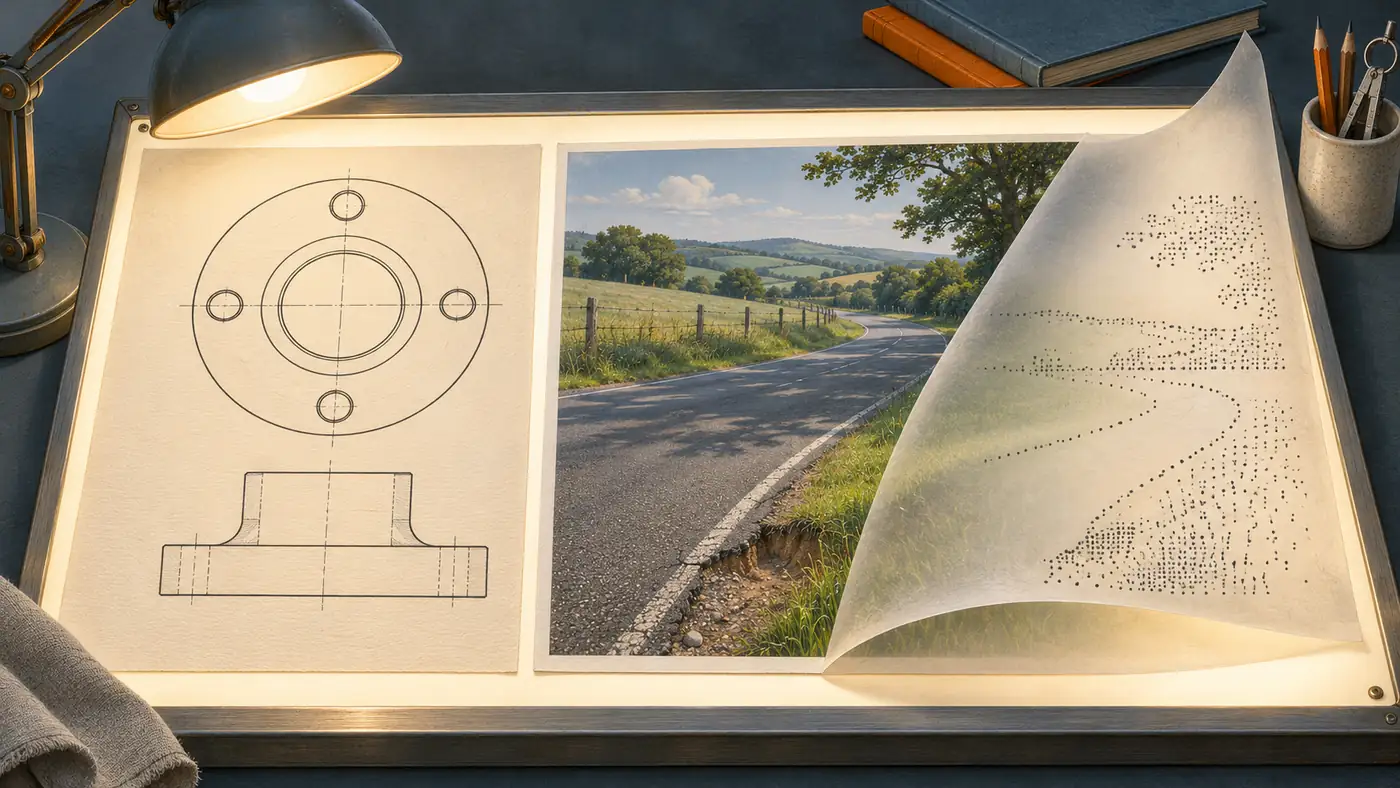
Schematic of original concept. The material in the figure is an illustration structure.
A road inspection report missed a depression in the pavement. The agent must identify it from site photos, then prepare an estimate using the classification manual and the contractor’s rates. Google DeepMind’s MKA technical report, released November 10, describes what happened when the direct image-viewing tool was removed. Gemini 4 Carbon could still extract the photos and even turn the light and dark patches of pavement into character art. Yet on several attempts it concluded that the report had missed nothing. For anyone bringing a multimodal model into a research workflow, there’s a practical question here: the file made it in, but did the detail that decides the answer survive? Technical Report, Appendix B
Which files should be paired with a floor plan
MKA was launched by Google DeepMind and Artificial Analysis. There is a building review question in the public sample questions, with five floor plans, two sections, four elevations, and a review specification on the desktop. The entrusting party only needs a presentation that lists the abnormality. To judge whether the opening of a door and window is consistent, the agent must first recognize which place it corresponds to in different views, and then pick out the differences that are worth reporting. Even if the complete text is drawn from each page, this layer of correspondence may have been lost. Public Tasks and Model Submissions
There are 200 questions in the official evaluation, which belong to ten industries, and each industry is 20. One hundred and seventy-six roads require the creation or revision of independent documents. Experts write grading rules for each question item by item, and the review program can not only open the page to see the layout, but also check the formula in the workbook. This allows researchers to distinguish between two types of "completed" handovers: one table has the correct column name, format and summation formula, and the other table also finds the accredited items from the source material. The two may get the format points at the same time, and the missing items will still be reflected in the content score. release note Technical Report, Sections 2 and 3
The same tool, how many points is worth on the two sets of questions
The author asks the same Gemini 4 Carbon to do the questions within the same running framework and the upper limit of 250 rounds, and only switches the tool to directly view the image. Both groups can run code, extract text, and use image processing libraries. Such an arrangement retains a realistic choice: when the original image cannot be read, the agent can take the time to think of another way. So the experiment detected two things at the same time, one is what else can be handed over in the end, and the other is how many steps can be taken to remedy it. Technical Report, Section 4.3
On the public gold-standard subset of GDPval, another benchmark for professional work, disabling direct image viewing changed the weighted share of requirements met by just +0.08 percentage points. The statistical interval included zero. On MKA, the same measure fell by 4.58 percentage points. For requirements that earlier models had struggled to meet consistently, the report’s Climb-WSR measure, the drop reached 5.94 percentage points. Meanwhile, the mean number of interaction rounds rose to 1.28 times its original value and the output token count to 1.40 times its original value. These scores measure requirements met within deliverables. They cannot tell us how many fewer jobs were completed. Technical Report, Table 5
Difficult items also have specific frames of reference. The author first asked four earlier models to do each three times. Only the entries that can be passed at least twice with the four models are grouped into a group that has been stably grasped. This division method helps to see which requirements the new model will miss, but it depends on the selected reference model; the most difficult judgment in the eyes of professionals may not happen to be in this group. Technical Report, Section 3.4
Why does the program energy out of the hole distance, but it misses the road pit
In a part processability review case, the model converts the parts of the drawing into dot matrix, scans the edges, and then converts the pixels into inches with the identified dimensions. Clear lines and holes can withstand this conversion. During the operation of the two closed viewing pictures, the key geometric problems were found once, and the other time, the gap between the hole and the hole, the feature and the wall surface was missed. When the drawings are enough to be regular, the script can indeed keep a part of the project judgment, but the energy is a certain size, and there is still a distance from the stable discovery of processing risks. Technical Report, Appendix B
The road photo gives the same way another ending. In the character painting, there is still a dark color in the pit; the model can't tell whether it is a subsided road or the texture of the asphalt itself. The authors report that the difficult item score of this question has dropped from 86.7% to 14.3%. Once the defect is missed, even if you can read the rate table, there is no way to estimate it. These two cases were selected by the author to explain the difference in behavior, and the probability of errors of all photos or mechanical drawings cannot be estimated with them. Technical Reports, Table 6 and Figure 9
Which part to review next?
A number worth checking individually is the 96.2% consistent rate of automatic review and expert judgment. Verify the coverage of fifty tasks, focus on extracting the higher weight scores, and balance the passing samples. Therefore, this number can help the reader to judge how reliable the review process is in the batch judgment. To know if it will let go of a report with a beautiful appearance, which happens to miss the key flaws, and trace the disagreements between the two parties on the items and whether those items will change the user's decision. Technical Report, Sections 3.3, 6
At present, the ten separate display questions can be viewed publicly. The input documents, task descriptions and scoring rules can be checked, and the two hundred official questions are kept by the partner. According to the interpretation of the public technical report, this retrieval did not find the results of the third party repeating the above viewing comparison. The most worth waiting for is the item-by-item record of another model on the same batch of materials: if it can also make up the size from the drawing, but repeatedly misses the defect that is not written in the log in the photo, there is even more reason to attribute this difference to the material itself. If it can stably make up for the leak-returning term, it is worth looking back on what kind of reading method the first model has chosen. public data card Evaluation entrance
References
- Google DeepMind Release Notes, November 10, 2026
- MKA technical report, highlighted in Table 5, Table 6 and Appendix B
- Artificial Analysis
- Ten MKA display questions and data cards released by Google
Apps by the author
I also build small tools for everyday life. Here are two of my apps:
- Daily Expense Journal: Track your income and spending, plan a budget and set savings goals. View on the App Store.
- One Small Action: Pick a small action that fits the time and energy you have today, then record how it felt and what you noticed. View on the App Store.
Find more articles and projects on my website: zffjzz.top. I’d love to hear how the apps work for you and what I could improve.